/// AI HUB
Dashboard News Models Tools Papers Repos Videos Companies Trending
Login

#Multimodal

2340 articles tagged with Multimodal

Latest Trending
Mastodon discussion 1h ago

Meituan has published the open weights of LongCat-2.5 under an MIT licence, so developers can run a multimodal coding ag...

Meituan has published the open weights of LongCat-2.5 under an MIT licence, so developers can run a multimodal coding agent in-house. It reads screenshots and video and scores 88.4...

Multimodal
18
Mastodon discussion 4h ago

Anthropic launches Claude Fable 5.2 & Mythos 5.2 šŸ”„ Faster coding, sharper reasoning, better vision. Claude Fable 5.2 cru...

Anthropic launches Claude Fable 5.2 & Mythos 5.2 šŸ”„ Faster coding, sharper reasoning, better vision. Claude Fable 5.2 crushes tough software engineering. Ready to level up? #AI

Anthropic Multimodal
9
Mastodon discussion 6h ago

Anthropic released Mythos 5.2 and Fable 5.2, with gains in coding, reasoning and vision. Fable's price drops to $8 per m...

Anthropic released Mythos 5.2 and Fable 5.2, with gains in coding, reasoning and vision. Fable's price drops to $8 per million input tokens, now below GPT-6 Astra. It's the first r...

OpenAI Anthropic Multimodal
9
Mastodon discussion 6h ago

Anthropic shipped Claude Mythos 5.2 and Fable 5.2, claiming better coding, reasoning and vision, with Fable cut to 8 USD...

Anthropic shipped Claude Mythos 5.2 and Fable 5.2, claiming better coding, reasoning and vision, with Fable cut to 8 USD per million input tokens and 30 percent faster replies. The...

Anthropic Multimodal
9
GitHub Trending repo 9h ago

AbdallahMabrouk1/Gradient_Zero: A Computer Vision and Robotics project focused on integrating intelligent visual perception with robotic systems using AI and machine learning technologies.

A Computer Vision and Robotics project focused on integrating intelligent visual perception with robotic systems using AI and machine learning technologies.

Multimodal
38
Mastodon discussion 10h ago

An open 8B model scored 80.9% on an astronomy benchmark. The paper puts that on par with GPT-4o.de Haan et al., Scientif...

An open 8B model scored 80.9% on an astronomy benchmark. The paper puts that on par with GPT-4o.de Haan et al., Scientific Reports 15 (2025): AstroSage-Llama-3.1-8B, trained on ast...

Multimodal Benchmark
9
Dev.to tutorial 14h ago

Why Tesseract Fails on Cursive Handwriting (And How We Built a Two-Tier Vision Pipeline in Node.js)

When building Holder—a personal information vault and second brain for screenshots, links, and...

Multimodal
20
Mastodon discussion 17h ago

DR-BOLT improves vision-language model efficiency by distinguishing fast and slow reasoning modes and correcting their m...

DR-BOLT improves vision-language model efficiency by distinguishing fast and slow reasoning modes and correcting their mismatch during training.Source: arXivhttps://arxiv.org/abs/2...

LLM Multimodal
9
Mastodon discussion 17h ago

Researchers introduced Glyph, an automated multistage framework that extracts features from multimodal and unstructured ...

Researchers introduced Glyph, an automated multistage framework that extracts features from multimodal and unstructured clinical data using foundation models and sparse autoencoder...

Multimodal
9
Mastodon discussion 17h ago

#Europe cannot ignore the US government’s new vision for research šŸ–Šļø Thomas JĆørgensenAs the tRump administration’s visio...

#Europe cannot ignore the US government’s new vision for research šŸ–Šļø Thomas JĆørgensenAs the tRump administration’s vision for research looks to let #AI guide tech development and r...

Multimodal
27
Mastodon discussion 17h ago

Flex-RSI is introduced as a benchmark for the recursive self-improvement of agents on vision and robotics tasks under a ...

Flex-RSI is introduced as a benchmark for the recursive self-improvement of agents on vision and robotics tasks under a fixed budget.Source: arXivhttps://arxiv.org/abs/2611.08946#M...

Multimodal Benchmark
9
Mastodon discussion 18h ago

ROSE is a risk-aware orthogonal subspace navigation framework for lifelong knowledge editing in multimodal large languag...

ROSE is a risk-aware orthogonal subspace navigation framework for lifelong knowledge editing in multimodal large language models.Source: arXiv cs.CLhttps://arxiv.org/abs/2611.09770...

Multimodal
9
GNews news 20h ago

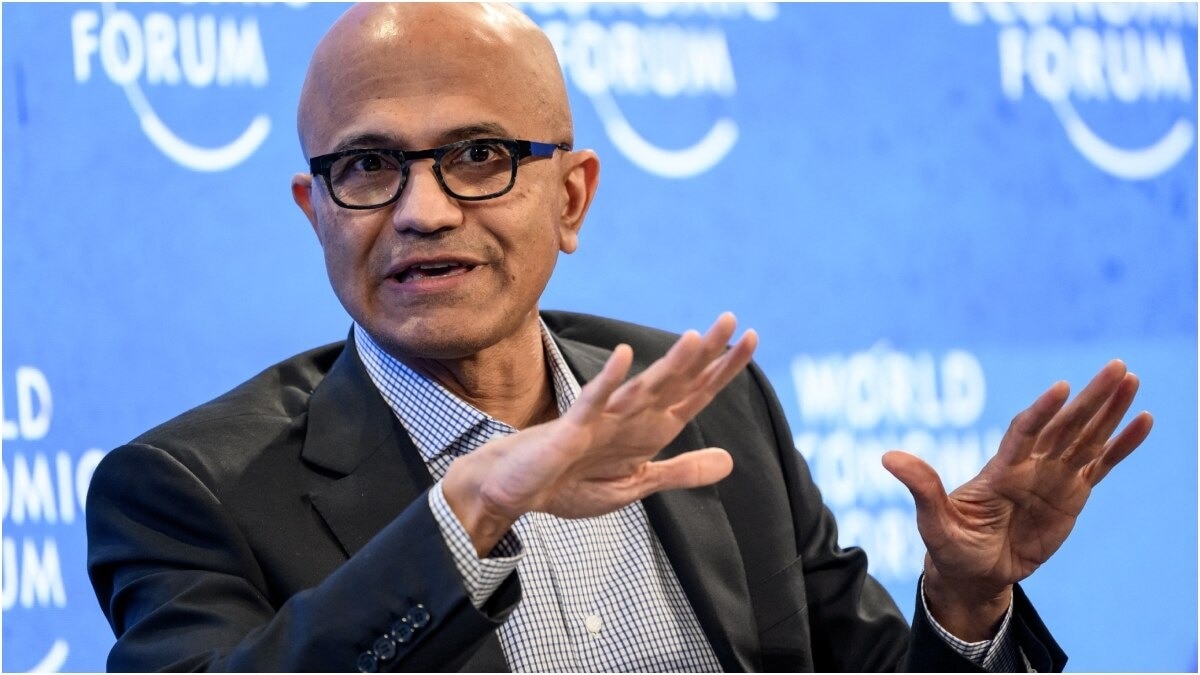
Microsoft's 60,000-employee exit offer and Nadella's vision of 20 million AI agents

Satya Nadella's vision of millions of AI agents has resurfaced after Microsoft's voluntary exit offer. The timing has renewed questions about how artificial intelligence could resh...

Microsoft Multimodal
18
Mastodon discussion 22h ago

ā€Musk, Altman and Amodei have created a vision of an AI future. What they haven’t done is built the technology that can ...

ā€Musk, Altman and Amodei have created a vision of an AI future. What they haven’t done is built the technology that can possibly support it. The version of AI that’s on sale now, l...

Multimodal
35
NewsData.io news 1d ago

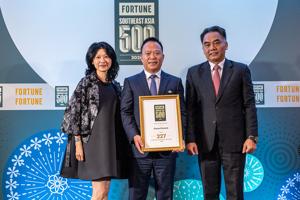
Stavian Group Showcases Its Infrastructure Vision for the AI Era at the Inaugural Fortune SEA500 Summit 2026

HO CHI MINH CITY, Vietnam, Nov. 8, 2026 /PRNewswire/ -- As Southeast Asia enters a new phase of growth shaped by artificial intelligence, digital transformation, evolving supply ch...

Multimodal
21
Mastodon discussion 1d ago

Jun–Sep 2026: GPT-4o — Undisclosed Evidence: $10k FinOps Deposits, Sentinel Suppress, RCA-72-FINAL, TAMP-46, Ongoing SEV...

Jun–Sep 2026: GPT-4o — Undisclosed Evidence: $10k FinOps Deposits, Sentinel Suppress, RCA-72-FINAL, TAMP-46, Ongoing SEV-0 Security Breach, and FTC–DOJ–ICOĀ Investigations 13 FEBRUA...

OpenAI Multimodal
9
Mastodon discussion 2d ago

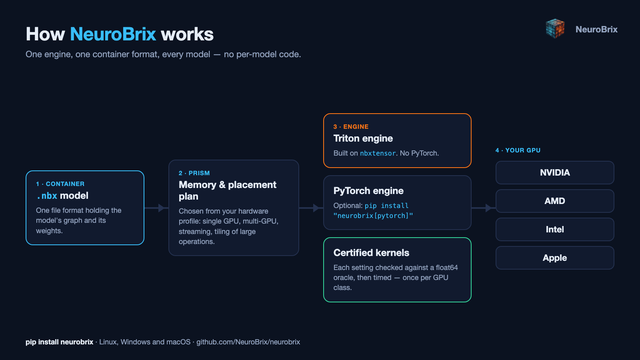
NeuroBrix 0.6 is out, our first stable release.One inference engine for 49 models in 9 families — language, code, vision...

NeuroBrix 0.6 is out, our first stable release.One inference engine for 49 models in 9 families — language, code, vision, omni, speech recognition, text-to-speech, image, video, up...

Multimodal
9
NewsData.io news 2d ago

Cambodia outlines three-point AI vision at 7th World Media Summit

Cambodia has shared three key principles for global media to ensure artificial intelligence supports professional journalism and serves the public interest. The post Cambodia outli...

Multimodal
21
GitHub Trending repo 2d ago

Turboheartblaze/resp-fortuna-vision-public-preview: šŸ‘ļø FortunaVision — chart-first market + treasury workstation, static, no keys: TradingView's open-source chart engine beside Fortuna's SVG engine, Auto Levels, regime, order flow, dealer gamma, drawings, indicator files, a command line, and a Treasury mode (chains, yields, stablecoins, holdings). Public preview of the private lane.

šŸ‘ļø FortunaVision — chart-first market + treasury workstation, static, no keys: TradingView's open-source chart engine beside Fortuna's SVG engine, Auto Levels, regime, order flow, ...

Multimodal Open Source
49
Mastodon discussion 3d ago

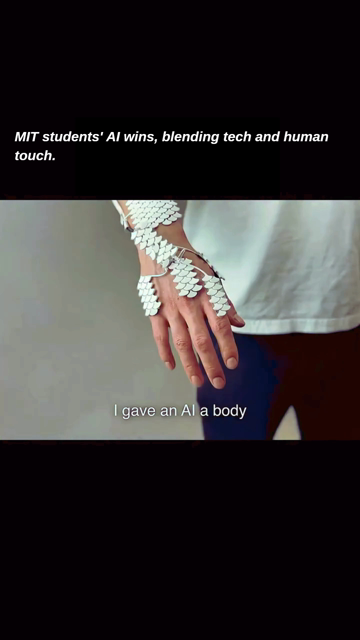
An look at MIT's "Human Operator," combining AI vision and electrical muscle stimulation for physical skill guidance. šŸ¤–A...

An look at MIT's "Human Operator," combining AI vision and electrical muscle stimulation for physical skill guidance. šŸ¤–As cyber-physical systems scale, we must reject centralized G...

Multimodal
9
Dev.to tutorial 3d ago

[Part 3] Your first steps in Computer Vision on AWS: deploying models for an ASL recognition app

This is the third and final part of the series "Your first steps in Computer Vision on AWS". If you...

Multimodal
43
Mastodon discussion 3d ago

Ant Group's Ling team has launched Ling-3.2-flash, a native multimodal model with 560 billion total parameters, 25 billi...

Ant Group's Ling team has launched Ling-3.2-flash, a native multimodal model with 560 billion total parameters, 25 billion active and a context window of up to one million tokens. ...

Anthropic Multimodal
18
Mastodon discussion 3d ago

Ant Group released Ling-3.2-flash on November 5 as a multimodal model that accepts text, images and video.Source: TechNo...

Ant Group released Ling-3.2-flash on November 5 as a multimodal model that accepts text, images and video.Source: TechNodehttps://technode.com/2026/11/06/ant-launches-ling-3-2-flas...

Multimodal
9
NewsData.io news 3d ago

Ajman Government Media Office unveils vision and programme for inaugural Ajman Media Forum 2026

An interactive programme featuring media innovation challenges, emerging technologies and data-driven dialogue AJMAN, UAE, Nov. 6, 2026 /PRNewswire/ -- The Ajman Government Media O...

Multimodal
21
Page 1 of 98 (2340 items) Next »
AI Hub // AI Intelligence Platform // LIVE FEED // Impressum // Datenschutz © 2026
0 new articles available