/// AI HUB
Dashboard News Models Tools Papers Repos Videos Companies Trending
Login

#Multimodal

2345 articles tagged with Multimodal

Latest Trending
Mastodon discussion Oct 16

Modality Self-Play is a training framework for multimodal foundation models based on proxy-mediated modality composition...

Modality Self-Play is a training framework for multimodal foundation models based on proxy-mediated modality composition.Source: arXivhttps://arxiv.org/abs/2610.20965#MachineLearni...
Multimodal
9
Mastodon discussion Oct 16

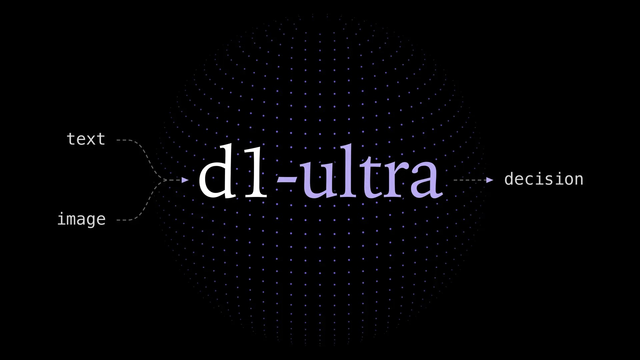
🎯 #LiquidAI released d1-ultra, a multimodal decision model for text and images, built for hard real-world cases like spo...

🎯 #LiquidAI released d1-ultra, a multimodal decision model for text and images, built for hard real-world cases like spotting a circuit board defect against its spec or checking a ...

Multimodal
9
Papers with Code paper Oct 16

Harnessing Textual Refusal Directions for Multimodal Safety

Safety in Multimodal Large Language Models (MLLMs) depends on unsafe multimodal data for post-training alignment or activation steering. However, such data is hard to collect, must...

Multimodal
21
Papers with Code paper Oct 16

MambaAct: Efficient Mamba Action Experts for Flow-Matching Vision-Language-Action Models

Vision-language-action (VLA) models have shown strong promise for generalist robotic manipulation, but their inference cost remains a major bottleneck for real-time control. This l...

Multimodal
21
Mastodon discussion Oct 15

Technology can help make the digital world more accessible. #AI powered tools such as Seeing AI use computer vision to h...

Technology can help make the digital world more accessible. #AI powered tools such as Seeing AI use computer vision to help people who are blind or have low vision understand the w...

Multimodal
9
Mastodon discussion Oct 15

📰 openKylin Outlines Its Vision for Reimagining Linux in the AI Era at Open Source Summit Europe 2026At Open Source Summ...

📰 openKylin Outlines Its Vision for Reimagining Linux in the AI Era at Open Source Summit Europe 2026At Open Source Summit Europe 2026, openKylin outlined its vision for transition...

Multimodal Open Source
9
GNews news Oct 15

VisionQuest X Review: Marvel Fans Discuss White Vision, Ultron, Tommy Shepherd - What Paul Bettany Show Means For MCU?

Marvel's VisionQuest premiere sparked discussion over White Vision's identity, Ultron's return and J.A.R.V.I.S.'s sacrifice. Following WandaVision and Agatha All Along, the new Pau...

Multimodal
18
Mastodon discussion Oct 15

Native multimodal pre-training trains a single model from scratch on text and multimodal data. Replacing image embedding...

Native multimodal pre-training trains a single model from scratch on text and multimodal data. Replacing image embeddings with padding token embeddings affects visual-content ablat...

Multimodal
9
Mastodon discussion Oct 15

DecisionRobust benchmarks robustness for JEV style decision models across text and vision.Source: arXiv cs.CLhttps://arx...

DecisionRobust benchmarks robustness for JEV style decision models across text and vision.Source: arXiv cs.CLhttps://arxiv.org/abs/2610.19118#MachineLearning

Multimodal
9
Dev.to tutorial Oct 15

FoodTruth: Exposing Packaged Food Deception with Open-Weight Vision AI

This is a submission for the Hacktoberfest Open-Source AI Challenge Week 2: Side Hustle ...

Multimodal
20
AI Blogs (RSS) news Oct 15

Welcome Muse Spark Open: open-weight frontier multimodal mixture-of-experts model from Meta

Multimodal
24
Papers with Code paper Oct 15

Intern-Decision: Efficient Multimodal Decision Making with Autoregressive Masked Language Modeling

Interactive agents repeatedly choose among a finite set of actions, labels, or ordinal outcomes. Generating a free-form response for each choice adds latency and complicates the in...

Multimodal
21
Papers with Code paper Oct 15

Skill-Decoupled On-Policy Expert Distillation for Unified Vision-Language Models

Reinforcement learning (RL) can elicit specialized visual capabilities in vision-language models (VLMs), yet jointly optimizing heterogeneous objectives often introduces cross-capa...

Multimodal
21
Papers with Code paper Oct 15

VLA-Δ: Learning Physical State Transition for Vision-Language-Action Models

Vision-language-action (VLA) models transfer semantic knowledge acquired through vision-language pretraining to robot control, achieving strong performance across various benchmark...

Multimodal
21
Papers with Code paper Oct 15

MMSearch-OPD: Easy Made Hard, Hard Made Learnable for Long-Horizon Multimodal Search Agents

Multimodal deep search is moving from short queries to long-horizon investigations that continually acquire evidence. However, training such agents remains constrained by limited c...

Multimodal
21
Papers with Code paper Oct 15

CoWorld Reasoner: Agentic Multimodal Reasoning with the Evolving Video World Model-Driven Harness

As Vision-Language Models (VLMs) advance, they are increasingly expected to perform spatiotemporal reasoning over motion, actions, and view changes beyond what the input images sho...

Multimodal Agents
21
Papers with Code paper Oct 15

Stuck on Shuffle: On Attribute-Object Binding in Vision-Language Models

Retrieval is a fundamental task in multimodal systems: given an image or text query, the goal is to find the most relevant images or texts in a collection, often using a shared emb...

Multimodal
21
Papers with Code paper Oct 15

Can Visual Generation Expand What Unified Multimodal Models Know?

Unified multimodal models (UMMs) receive image-generation supervision that exposes them to visual information not fully documented in text. Can learning to generate images expand w...

Multimodal
21
Papers with Code paper Oct 15

OmniXRef: A Unified Framework for Multimodal Multi-Reference Video Editing

Creative intent in video editing can be expressed through text instructions (e.g., "remove the people"), image references (e.g., subject appearance), video references (e.g., camera...

Multimodal
21
Mastodon discussion Oct 14

ActTune: Action-Aware Precision and GPU Operating-Point Adaptation for Energy-Efficient Vision-Language-Action Inference...

ActTune: Action-Aware Precision and GPU Operating-Point Adaptation for Energy-Efficient Vision-Language-Action Inference#LLM #Roboticshttps://hgpu.org/?p=31388

Multimodal AI Hardware
9
Mastodon discussion Oct 14

NEURA Robotics unveiled Neuron AI, a robot foundation model that processes touch, sound, and memory alongside vision. Th...

NEURA Robotics unveiled Neuron AI, a robot foundation model that processes touch, sound, and memory alongside vision. The model runs locally on five robot types. No benchmarks publ...

LLM Multimodal Robotics
9
NewsData.io news Oct 14

WoundZoom Featured on CIO Bulletin Cover, Highlighting Vision for the Future of Intelligent Wound Care

CEO Mark Lacerte Shares How the Wound Performance Platform Is Transforming Wound Care Through AI, Connected Clinical Workflows and Real-Time Analytics

Multimodal
21
Mastodon discussion Oct 14

MDN-VJEPA is a multimodal probabilistic JEPA that instantiates the latent predictor as a mixture density network represe...

MDN-VJEPA is a multimodal probabilistic JEPA that instantiates the latent predictor as a mixture density network representing future states with a Gaussian mixture. Controlled expe...

Multimodal
9
Papers with Code paper Oct 14

Seeing, Maintaining, and Learning: The Evolution of Multimodal Agent Memory

Multimodal models and agents have emerged to enable AI systems to learn from and interact with the real world more like humans by integrating information across multiple modalities...

Multimodal
21
« Previous Page 11 of 98 (2345 items) Next »
AI Hub // AI Intelligence Platform // LIVE FEED // Impressum // Datenschutz © 2026
0 new articles available