/// AI HUB
Dashboard News Models Tools Papers Repos Videos Companies Trending
Login

#Multimodal

2356 articles tagged with Multimodal

Latest Trending
Papers with Code paper Oct 8

SpaceCast-Bench: Evaluating Predictive Spatial Reasoning in Vision-Language Models

Existing spatial reasoning benchmarks mainly test spatial perception: reading off relations already visible in the input. Yet real-world spatial intelligence demands predictive spa...

Multimodal
21
Papers with Code paper Oct 8

One Block, Multiple Depths: Recurrent Vision Transformers with Depth-Programmed Experts

In this work, we show that a single Transformer block, applied recurrently, can match the accuracy of a full-depth vision encoder at comparable inference FLOPs without intermediate...

Multimodal
21
Papers with Code paper Oct 8

DataVista: Diagnosing Multimodal LLMs on Data Video Understanding

Data video is a media form that integrates data visualization with video narrative, widely adopted in news reporting and business analysis. Compared with general video understandin...

Google Multimodal
21
Papers with Code paper Oct 8

Humanity's Sixth Sense: Benchmarking Intuitive Visual Reasoning in Multimodal Models

Humans perceive far more in a scene than what is explicitly depicted: a single glance captures past causes and future trajectories; a quick peek determines if a vehicle can fit bet...

Multimodal
21
Papers with Code paper Oct 8

WOVEN: Weaving Visual World Modeling into Multimodal LLMs

Multimodal large language models (MLLMs) struggle with spatial, embodied, physical, and temporal reasoning. We hypothesize that these failures reflect a shared deficit in visual tr...

OpenAI Multimodal
21
Papers with Code paper Oct 8

Super-Resolution in The Right Latent Space: A Frozen Vision-Foundation Substrate

In an image latent space, the embeddings of high-resolution, natural, and sharp images form a manifold. Degradation of high-resolution images pushes their embeddings off this manif...

Multimodal
21
GNews news Oct 8

Microsoft pushes AI vision with new, expensive Surface laptop

SAN FRANCISCO, United States — Microsoft is pushing a 'hybrid intelligence' future with a new Surface Ultra laptop that runs on Nvidia artificial intelligence (AI) chips and will c...

Microsoft Multimodal
18
Mastodon discussion Oct 7

EmbeddingGemma 2: Multimodal search for end devicesGoogle has released EmbeddingGemma 2. The model maps text, code, imag...

EmbeddingGemma 2: Multimodal search for end devicesGoogle has released EmbeddingGemma 2. The model maps text, code, images, audio, and video into a common vector space.https://www....

Google Multimodal
18
Mastodon discussion Oct 7

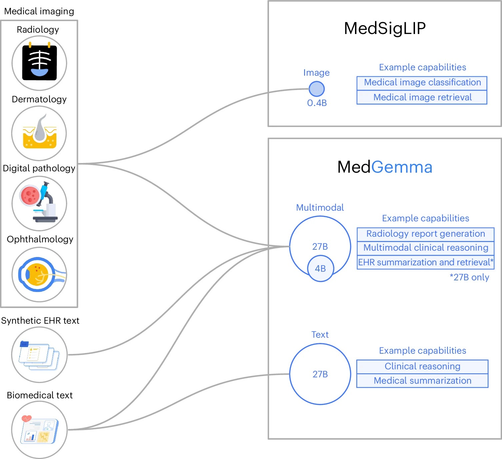
From #Nature: "An open vision-language model for diverse #medical applications" https://www.nature.com/articles/s41591-0...

From #Nature: "An open vision-language model for diverse #medical applications" https://www.nature.com/articles/s41591-026-04626-w#AI #Medgemma #LLM #ComputerVision

LLM Multimodal
18
AI Blogs (RSS) news Oct 7

Multimodal open d1 decision models for the edge

Multimodal
24
GitHub Trending repo Oct 7

Gene-Weaver/LeafMachine3: LeafMachine3 is a modular suite of computer vision and machine learning algorithms that enables efficient identification, location, and measurement of vegetative, reproductive, and archival components from digital plant datasets.

LeafMachine3 is a modular suite of computer vision and machine learning algorithms that enables efficient identification, location, and measurement of vegetative, reproductive, and...

Multimodal
38
Mastodon discussion Oct 7

Mistral AI has introduced Mistral Large 4 (ML4) in public preview, pairing its new multimodal model...#ai #automation #t...

Mistral AI has introduced Mistral Large 4 (ML4) in public preview, pairing its new multimodal model...#ai #automation #tools #mistral #software #coding #development #engineering #i...

Mistral Multimodal
24
Dev.to tutorial Oct 7

FLUX 3 Review 2026: Black Forest Labs' Multimodal Video Model, Priced Per Second

FLUX 3 is Black Forest Labs\u2019 first multimodal foundation model\u200a\u2014\u200avideo with native audio, images, and action prediction for robotics\u200a\u2014\u200abuilt on a...

Image Generation Multimodal
28
Mastodon discussion Oct 7

EmbeddingGemma 2: An open, lightweight multimodal embedding modelhttps://blog.google/innovation-and-ai/technology/develo...

EmbeddingGemma 2: An open, lightweight multimodal embedding modelhttps://blog.google/innovation-and-ai/technology/developers-tools/embeddinggemma-2/#ai #google

Google Multimodal
9
Dev.to tutorial Oct 7

Edge AI with .NET, Part 3: Vision OCR You Can Actually Trust

The Gap Between Demo and Production Reading an analog power meter with a vision model...

Multimodal
12
YouTube video Oct 7

日本初のDolby Vision+Atmosシアター誕生 #Shorts

Shorts #生成AI #ニュース #CreativeAIDigest ▽ 日本初のDolby Vision+Atmosシアター、シネマサンシャイン三郷に6日オープン ...

Multimodal
30
Dev.to tutorial Oct 7

Building a Resilient Vision-Guided Desktop RPA Engine in Python (Without $15k/yr Enterprise Licenses)

Ditch brittle coordinate clicks and predatory RPA fees. Build a self-healing, local vision-guided GUI automation engine in Python.

Multimodal
12
Mastodon discussion Oct 7

Google unveiled EmbeddingGemma 2, an open lightweight multimodal embedding model that supports on-device AI.Source: Gadg...

Google unveiled EmbeddingGemma 2, an open lightweight multimodal embedding model that supports on-device AI.Source: Gadgets 360https://www.gadgets360.com/ai/news/google-embeddingge...

Google Multimodal
9
Mastodon discussion Oct 7

Mistral AI officially launched the Mistral Large 4 public preview. Discover how this trillion-parameter multimodal model...

Mistral AI officially launched the Mistral Large 4 public preview. Discover how this trillion-parameter multimodal model rivals top closed-source systems.#MistralAI #MistralLarge4 ...

Mistral Multimodal
27
Mastodon discussion Oct 7

Discover Google EmbeddingGemma 2, a lightweight multimodal AI model bringing powerful text, image, video, and audio proc...

Discover Google EmbeddingGemma 2, a lightweight multimodal AI model bringing powerful text, image, video, and audio processing directly to edge devices.#EmbeddingGemma2 #GoogleAI #...

Google Multimodal
24
NewsData.io news Oct 7

Brian Evergreen is Corporate America’s AI coach. His message: ‘AI doesn’t have vision. Leaders do.’ Are you ready to hear it?

Brian Evergreen— AI executive coach, chess prodigy, and former choirboy—wants me to articulate a vision for my future. As the waiter replaces our appetizers with entrées, I dodge b...

Multimodal
21
Mastodon discussion Oct 7

🚀 Fastest-growing AI projects today1. Notable among these efforts repositories that focus on system design, multimodal d...

🚀 Fastest-growing AI projects today1. Notable among these efforts repositories that focus on system design, multimodal datase...2. The repository "ai-system-design" by amitshekhari...

Multimodal
9
Mastodon discussion Oct 7

Mistral debuts a 1T-parameter open-weight model, OpenAI releases 722 math manuscripts, and Google ships a new multimodal...

Mistral debuts a 1T-parameter open-weight model, OpenAI releases 722 math manuscripts, and Google ships a new multimodal embedding model. Lambda eyes a $4B raise backed by one majo...

OpenAI Google Mistral
9
NewsData.io news Oct 7

Blade Runner is still the greatest sci-fi film about AI—and why our future won't match its vision

Ridley Scott’s 1982 masterpiece Blade Runner offers sci-fi's most hauntingly atmospheric vision of artificial intelligence, raising profound philosophical questions about humanity ...

Multimodal
21
« Previous Page 15 of 99 (2356 items) Next »
AI Hub // AI Intelligence Platform // LIVE FEED // Impressum // Datenschutz © 2026
0 new articles available