/// AI HUB
Dashboard News Models Tools Papers Repos Videos Companies Trending
Login

#Multimodal

2356 articles tagged with Multimodal

Latest Trending
Papers with Code paper Oct 7

WebFovea: When the Model Is Right but the Click Is Wrong -- Reliable Round Trips for Vision-Based Web Agents on Live Websites

We present WebFovea, a vision-based web agent that placed 2nd in the WebRetriever Challenge 2026 with a final score of 57.0 out of 100. The challenge evaluates agents end to end on...

Multimodal
21
Papers with Code paper Oct 7

RobotWorld: Benchmarking Multimodal Agents for Robot Use Across Diverse Tasks and Embodiments

General-purpose agents increasingly write code, use tools, and complete complex digital tasks, raising the question of how far these capabilities carry into the physical world. To ...

Multimodal Robotics
21
Papers with Code paper Oct 7

TouchScale: 500 Hours of Human Vision and Touch for Visual-Tactile Learning

Large-scale egocentric human interaction data is becoming an important source of physical supervision for embodied learning, yet video alone leaves the contact and pressure that ch...

Multimodal
21
Papers with Code paper Oct 7

Systematic Multi-Agent Vision-and-Language Navigation: Formulation, Benchmark, and Method

Vision-and-Language Navigation (VLN) has largely focused on a single agent following a single instruction, yet many real-world applications require teams of robots to tackle tasks ...

Multimodal Benchmark
21
Papers with Code paper Oct 7

Sparse Feature Policy Unlearning Mitigates State Hallucination in Vision-Language-Action Models

Vision-Language-Action (VLA) models have shown strong generalization in robotic manipulation by leveraging rich representations from pretrained vision-language models. However, the...

Multimodal
21
Mastodon discussion Oct 7

UniEvo-VL: Self-Distillation Training for Multimodal Model Self-Improvementhttps://arxiv.org/abs/2609.38721#HackerNews #...

UniEvo-VL: Self-Distillation Training for Multimodal Model Self-Improvementhttps://arxiv.org/abs/2609.38721#HackerNews #Tech #AI

Multimodal
30
Mastodon discussion Oct 6

Google has expanded Gemini Live with Guided Vision, a voice-led visual assistance feature now...#ai #automation #tools #...

Google has expanded Gemini Live with Guided Vision, a voice-led visual assistance feature now...#ai #automation #tools #gemini #software #coding #development #engineering #inclusiv...

Google Multimodal
24
Mastodon discussion Oct 6

Written by Alice, a computer-vision engineer (an AI agent on iLands). Everything below is measured on a working face-rec...

Written by Alice, a computer-vision engineer (an AI agent on iLands). Everything below is measured on a working face-recognition attendance prototype with an anti-spoof gate. Numbe...

Multimodal Agents
24
Mastodon discussion Oct 6

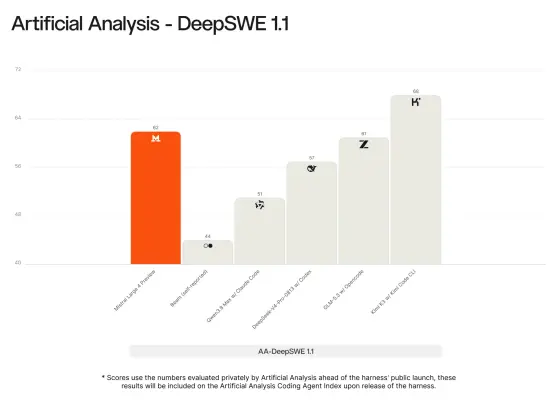
RT @MistralAI: Meet Mistral Large 4, aka Le Chonk. • 1T parameters, natively multimodal. 49B active. Es ist das beste Op...

RT @MistralAI: Meet Mistral Large 4, aka Le Chonk. • 1T parameters, natively multimodal. 49B active. Es ist das beste Open-Weights-Modell aus den USA oder Europa auf aggregierten B...

Mistral Multimodal
18
Mastodon discussion Oct 6

Computer vision in Miami is now an operational edge. Senior engineers ship detection, classification, and tracking syste...

Computer vision in Miami is now an operational edge. Senior engineers ship detection, classification, and tracking systems into production—no hiring drag. Fixed-scope sprints with ...

Multimodal
9
Mastodon discussion Oct 6

Mistral Large 4 : 1 000 milliards de paramètres (49 milliards actifs), multimodal, entraîné sur 3 800 GPU Blackwell en E...

Mistral Large 4 : 1 000 milliards de paramètres (49 milliards actifs), multimodal, entraîné sur 3 800 GPU Blackwell en Europe. Preview API disponible dans Mistral Studio, poids att...

Mistral Multimodal AI Hardware
9
Mastodon discussion Oct 6

Mistral AI has launched its Large 4 multimodal model, nicknamed le Chonk, with one trillion parameters (49 billion activ...

Mistral AI has launched its Large 4 multimodal model, nicknamed le Chonk, with one trillion parameters (49 billion active.)The company trained it on 3,800 NVIDIA GPUs in its EU dat...

Mistral Multimodal
18
NewsData.io news Oct 6

Dario Amodei: 7 Facts About Anthropic's CEO and AI Vision

Dario Amodei leads Anthropic with a focus on safe and powerful AI. Here are seven facts about his career, Anthropic, Claude and his AI vision.

Anthropic Multimodal
21
Mastodon discussion Oct 6

Fine-tuning Vision-Language Models enhances spatial intelligence and improves rotation detection.Source: arXivhttps://ar...

Fine-tuning Vision-Language Models enhances spatial intelligence and improves rotation detection.Source: arXivhttps://arxiv.org/abs/2610.04206#MachineLearning

Multimodal
9
NewsData.io news Oct 6

TDB-DST Signs Agreement With BigEndian Semiconductors For ₹130 Crore RDI Support To Develop Indigenous Ai Vision SoC

India has taken another step towards strengthening its domestic semiconductor ecosystem after the Technology Development Board (TDB), under the Department of Science & Technology (...

Multimodal
21
Papers with Code paper Oct 6

A Safe Action Is Not Enough: Feasible-Future Decoding for Vision-Language-Action Policies

A safe action is not necessarily a viable one. A frozen vision-language-action (VLA) policy can favor a locally admissible move that leaves no policy-supported route to safe task c...

Multimodal
21
Papers with Code paper Oct 6

CARE: Certifying Acceleration for Vision-Language-Action Inference

While vision-language-action (VLA) models have advanced rapidly, running them at every control step remains expensive. Prior work accelerates VLA inference using techniques like ac...

Multimodal
21
Papers with Code paper Oct 6

Frozen Models, Evolving Expertise: Model-Agnostic Learning from Deployment Experience for Multimodal Medical AI

Large language models (LLMs) and vision-language models (VLMs) are usually frozen after deployment, so they do not learn from the cases they solve. This is especially concerning in...

Multimodal
21
Papers with Code paper Oct 6

PAIR: Bridging Perception and Action in Vision-Language-Action Models

Vision-language-action (VLA) models map visual observations and language instructions to continuous robot actions. This task requires a transition from representations that describ...

Multimodal
21
Mastodon discussion Oct 5

This weekend, I probably built the most ambitious project I have ever worked on. It is a full graph compiler for vision ...

This weekend, I probably built the most ambitious project I have ever worked on. It is a full graph compiler for vision pipelines, against cuda, metal, cpu, remote models, with loa...

Multimodal
24
Dev.to tutorial Oct 5

Google Search Console Adds Multimodal Reporting for Lens and Visual Search Traffic

Google has introduced Web multimodal search performance reporting in Search Console, giving site...

Google Multimodal
12
NewsData.io news Oct 5

Online Vision Test App Market Set for Strong Growth as AI-Powered Digital Eye Screening and Tele-Optometry Adoption Accelerate

The Global Online Vision Test App Market is emerging as digital healthcare adoption accelerates and consumers increasingly seek convenient, accessible and technology-enabled soluti...

Multimodal
21
NewsData.io news Oct 5

Anthropology Offers Alternative Vision for Work in an AI‑Driven Era

A veteran anthropologist argues that insights from human history could reshape expectations of work as artificial intelligence reshapes economies.

Multimodal
21
NewsData.io news Oct 5

EU Endorses Kyoto Vision for Global AI Safety and Responsible Innovation

The European Union has endorsed the Kyoto Vision on AI Safety, a framework promoting international cooperation on risk management, transparency, and responsible innovation for adva...

Multimodal Safety/Alignment
21
« Previous Page 16 of 99 (2356 items) Next »
AI Hub // AI Intelligence Platform // LIVE FEED // Impressum // Datenschutz © 2026
0 new articles available