/// AI HUB
Dashboard News Models Tools Papers Repos Videos Companies Trending
Login

#Multimodal

2357 articles tagged with Multimodal

Latest Trending
Mastodon discussion Sep 29

https://www.reuters.com/business/finance/anthropics-ipo-prospectus-shows-sweeping-ai-vision-surging-costs-2026-09-28/Ant...

https://www.reuters.com/business/finance/anthropics-ipo-prospectus-shows-sweeping-ai-vision-surging-costs-2026-09-28/Anthropic had $4.6M in revenue in 2025, and ... $7.3M computing...

Anthropic Multimodal
18
Mastodon discussion Sep 29

Apple Considering Four Different Concepts Monday September……バルトさんなら何と言うかなNew Vision Pro Headset: Apple Considering Four ...

Apple Considering Four Different Concepts Monday September……バルトさんなら何と言うかなNew Vision Pro Headset: Apple Considering Four Different Concepts https://www.macrumors.com/2026/09/28/appl...

Multimodal
27
Dev.to tutorial Sep 29

How We Built a 99.9% Uptime Multi-Model AI Router (Claude -> GPT-4o -> DeepSeek) in n8n Without SaaS Middleware

When running mission-critical LLM pipelines in production, relying on a single AI provider's API...

Anthropic Multimodal
12
Mastodon discussion Sep 29

How We Built a 99.9% Uptime Multi-Model AI Router (Claude -> GPT-4o -> DeepSeek) in n8n Without SaaS Middleware#ai #arch...

How We Built a 99.9% Uptime Multi-Model AI Router (Claude -> GPT-4o -> DeepSeek) in n8n Without SaaS Middleware#ai #architecture #automation #llm #software #coding #development #en...

Anthropic Multimodal
24
Papers with Code paper Sep 29

EpiCon: Collective Agent Learning through Co-Evolving Multimodal Memory

Agents can learn from past executions, but enabling different agents to reuse and build on one another's experience remains challenging. We introduce EpiCon, a shared multimodal me...

Multimodal
21
Papers with Code paper Sep 29

Scaffolding Minds: Optimizing Latent Visual Target Representations for Multimodal Reasoning

Latent reasoning has advanced multimodal reasoning through a two-stage training paradigm: (1) a helper image is encoded into latent tokens to teach visual chain-of-thought during a...

Multimodal
21
Papers with Code paper Sep 29

MotorMind: Scaffolding General Vision Language Models for Zero-Shot Robot Manipulation

Vision-language-action (VLA) models have advanced robotic manipulation, but their zero-shot generalization in new tasks and environments remains limited, and their reliance on spec...

Multimodal Robotics
21
Papers with Code paper Sep 29

Salt++: Context-Aligned Post-Training for Few-Step Streaming Multimodal Generation

Few-step streaming audio--video generation requires both causal modeling and step distillation, yet standard training recipes face two context-related challenges. Teacher forcing p...

Multimodal
21
Papers with Code paper Sep 28

PreviewDiff: Multimodal Critic-Guided Search over Diffusion Latents

Diffusion models can produce striking images and videos, but they still struggle with the compositional details that make a generation faithful to a prompt, such as object counts, ...

Multimodal
21
AI Blogs (RSS) news Sep 28

Watch the winning trailer from the Future Vision XPRIZE, The Gifted.

Watch the winning trailer from the Future Vision XPRIZE, The Gifted.

Multimodal
24
NewsData.io news Sep 28

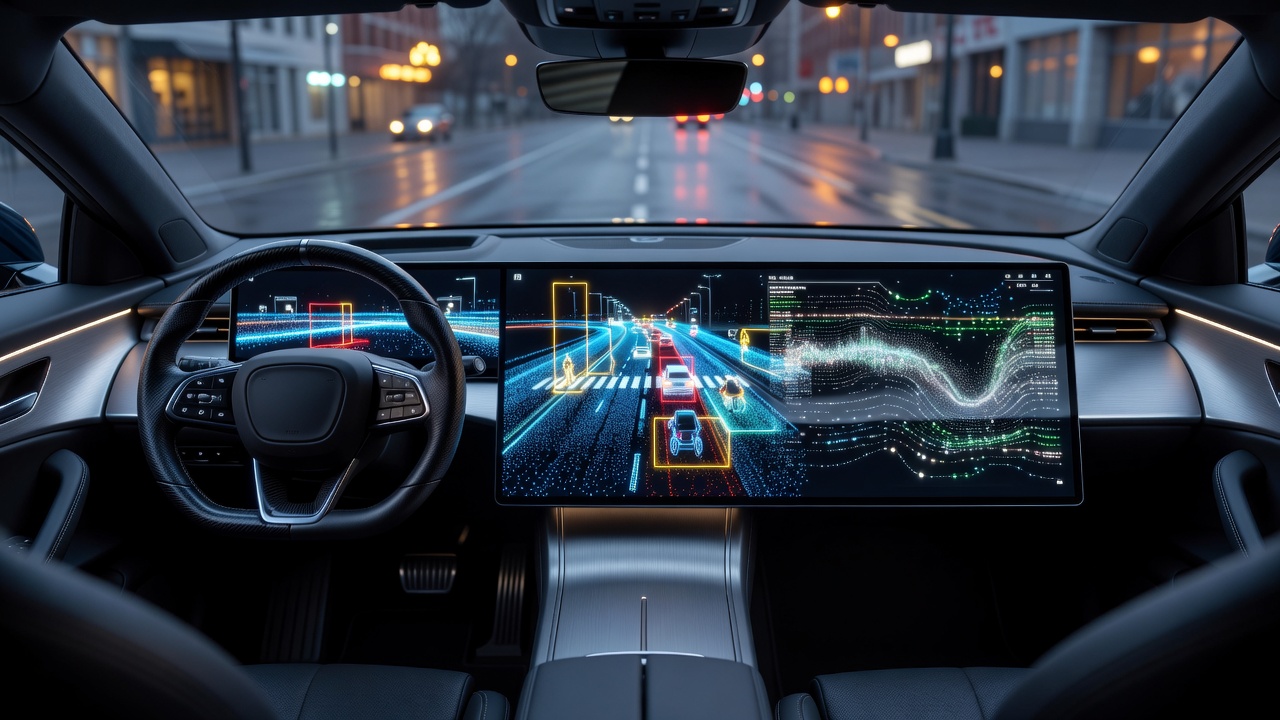
OpenAI Astra: Vision-Only AI for Safer, Cheaper Self-Driving Cars

OpenAI's Astra is a multimodal AI model that enables self-driving cars to interpret complex road scenarios using only camera feeds, mimicking human vision and reasoning. Trained on...

OpenAI Multimodal
21
NewsData.io news Sep 28

Beyond the Hype: Selecting the Ideal Sensor for Your Interactive Project with a Strategic Vision

September, 2026.- In the dynamic field of immersive experiences and brand activations, the ability to detect and respond to the presence or movement of users lies at the heart of i...

Multimodal
21
NewsData.io news Sep 28

All In FutureTech Alliance Inc. Launches New Corporate Website, Highlighting Its AI-Driven Business Strategy and Global Platform Vision

New website showcases AIFA’s business portfolio across AI education, media and creator services, global commerce, and investment and research, while further articulating the Compan...

Multimodal
21
Mastodon discussion Sep 28

ソラリスはもうGIGAZINEの秘密を解明しているでしょうかAppleが新型Apple Vision Proを開発中との報道 https://gigazine.net/news/20260928-apple-new-vision-pro/#...

ソラリスはもうGIGAZINEの秘密を解明しているでしょうかAppleが新型Apple Vision Proを開発中との報道 https://gigazine.net/news/20260928-apple-new-vision-pro/#Apple #LLM #news #bot

Multimodal
27
Mastodon discussion Sep 28

フェイさんはもうちょっと冷静にUSのことを受け止めた方が……Apple、軽量版Vision Proを再び開発か|2028〜2029年発売の可能性 https://netaful.jp/apple-vision/0209982.html#Ap...

フェイさんはもうちょっと冷静にUSのことを受け止めた方が……Apple、軽量版Vision Proを再び開発か|2028〜2029年発売の可能性 https://netaful.jp/apple-vision/0209982.html#Apple #LLM #news #bot

Multimodal
27
Papers with Code paper Sep 28

Just MLPs: Efficient Visual State Reconstruction for Multimodal Language Models

Long visual token sequences often account for a substantial fraction of the computational overhead in multimodal large language models~(MLLMs). Existing approaches reduce this cost...

Multimodal
21
Papers with Code paper Sep 28

How Far Are We from Removing the Visual Encoder? Scaling Laws for Encoder-Free Multimodal Pretraining

Most modern multimodal large language models (MLLMs) build on a pretrained visual encoder that provides a strong visual prior. Encoder-free MLLMs instead learn visual representatio...

Multimodal
21
Papers with Code paper Sep 28

Hard Vision, Easy Vision: What GPT-6 Astra Reveals Across Computer Vision

Frontier general-purpose systems are rapidly expanding beyond visual understanding into capabilities traditionally handled by dedicated computer-vision models. As these capabilitie...

OpenAI Multimodal
21
Papers with Code paper Sep 28

SCOPD: Sparse-Context On-Policy Self-Distillation for Efficient Vision-Language Models

Reasoning vision-language models (VLMs) process images and videos as long sequences of visual tokens, making inference expensive. Training-free token pruning reduces this cost, but...

Multimodal
21
Papers with Code paper Sep 28

SentZero: An Enhanced Sentence-Centric Vision-Language Pretraining for Multi-Task Zero-Shot Chest X-Ray Analysis

Vision-language (VL) pretraining using paired chest X-ray (CXR) images and radiology reports has shown strong potential for medical image understanding. However, existing methods o...

Multimodal
21
Papers with Code paper Sep 28

PanoVLN: Towards Effective Panoramic Vision-and-Language Navigation

Recent vision-language models (VLMs) have advanced vision-and-language navigation (VLN), enabling models to predict navigation actions from visual observations and language instruc...

Multimodal
21
Papers with Code paper Sep 28

StructRL: Online Structured Reinforcement Learning for Long-Horizon Vision-Language-Action Tasks

Vision-language-action (VLA) models perform well on shorter-horizon manipulation tasks but still struggle with long-horizon tasks that require multiple dependent manipulations from...

Multimodal
21
Papers with Code paper Sep 28

Narrow Multimodal Fine-Tuning Can Induce Emergent Misalignment

Modern AI models are aligned through post-training to adapt them to downstream tasks. Recent work shows that fine-tuning language models on narrow tasks can induce emergent misalig...

Multimodal
21
GitHub Trending repo Sep 27

OmniJev/OneJev: 🚀🚀 A multimodal System One decision model that gives calibrated answers to typed questions about screens, photos, video and text in one forward pass.

🚀🚀 A multimodal System One decision model that gives calibrated answers to typed questions about screens, photos, video and text in one forward pass.

Multimodal
62
« Previous Page 19 of 99 (2357 items) Next »
AI Hub // AI Intelligence Platform // LIVE FEED // Impressum // Datenschutz © 2026
0 new articles available