/// AI HUB
Dashboard News Models Tools Papers Repos Videos Companies Trending
Login

#Multimodal

2357 articles tagged with Multimodal

Latest Trending
Mastodon discussion Aug 27

The WeChat team open-sourced WeMM-Embedding for multimodal search and recommendation.Source: TechNodehttps://technode.co...

The WeChat team open-sourced WeMM-Embedding for multimodal search and recommendation.Source: TechNodehttps://technode.com/2026/08/27/wechat-team-open-sources-wemm-embedding-for-mul...

Multimodal
9
Mastodon discussion Aug 27

Dr. Elissa Kreiss discusses in a new podcast why the real challenge for multimodal AI is figuring out what information m...

Dr. Elissa Kreiss discusses in a new podcast why the real challenge for multimodal AI is figuring out what information matters most! 👇📺 https://www.youtube.com/watch?v=jtQq8NspkY4🎧...

Multimodal
9
Mastodon discussion Aug 27

🔦 AI for Beginners: Microsoft's 12-week curriculum covers neural networks, symbolic AI, and computer vision. With an Olu...

🔦 AI for Beginners: Microsoft's 12-week curriculum covers neural networks, symbolic AI, and computer vision. With an Olud Pulse of 49/100, it's a solid starting point. See the full...

Microsoft Multimodal
9
Mastodon discussion Aug 27

Alibaba has open-sourced Qwen3.8-Flash, a multimodal mixture-of-experts model with 125 billion parameters but only 6 bil...

Alibaba has open-sourced Qwen3.8-Flash, a multimodal mixture-of-experts model with 125 billion parameters but only 6 billion activated per token. Training cost is about one-ninth t...

Multimodal
18
Mastodon discussion Aug 27

🚀 Fastest-growing AI projects today1. Additionally, there considerable interest in robotics and multimodal data processi...

🚀 Fastest-growing AI projects today1. Additionally, there considerable interest in robotics and multimodal data processing, i...2. Cybermes by Zyrexnn/Cybermes stands out with an i...

Multimodal
9
Mastodon discussion Aug 27

Harvard: A Smartphone Navigation App for People with Blindness and Low Vision. “Engineers at the John A. Paulson School ...

Harvard: A Smartphone Navigation App for People with Blindness and Low Vision. “Engineers at the John A. Paulson School of Engineering and Applied Sciences (SEAS) have invented a n...

Multimodal
18
Papers with Code paper Aug 27

Aphanta: Diagnosing Task-Aligned Image-Edited Intermediates for Multimodal Reasoning

Explicit visual intermediates can help multimodal large language models (MLLMs) externalize spatial evidence and updated visual states, but their utility depends on whether an imag...

Multimodal
21
Papers with Code paper Aug 27

Beyond Data Scaling: Representation-Centric Continued Pre-training for Vision-Language-Action Models

Scaling robot data is crucial for building generalist Vision-Language-Action (VLA) models, yet robot trajectories are harder to scale than web-scale image-text data because embodie...

Multimodal
21
Mastodon discussion Aug 26

Z.ai introduces GLM-5.3-Flash, a natively multimodal model with 320B total and 18B active parameters. It outperforms GLM...

Z.ai introduces GLM-5.3-Flash, a natively multimodal model with 320B total and 18B active parameters. It outperforms GLM-5.2 in coding benchmarks using a hybrid attention architect...

Multimodal
9
Mastodon discussion Aug 26

Alibaba has released Qwen3.8-Flash-Next, a 125B multimodal Mixture-of-Experts model with just 6B active parameters. The ...

Alibaba has released Qwen3.8-Flash-Next, a 125B multimodal Mixture-of-Experts model with just 6B active parameters. The release previews Qwen4 architecture and reportedly trains at...

Multimodal
9
Dev.to tutorial Aug 26

GLM-5.3-Flash: Z.ai Reveals Ox Alpha Was Its Open Multimodal Model

For the past week, developers have been puzzling over a model called Ox Alpha. It appeared on...

Multimodal
12
Mastodon discussion Aug 26

[abo] ⋅ Islam, judéité, chrétienté : les LLM en disent aussi long sur notre vision des religions− https://next.ink/25309...

[abo] ⋅ Islam, judéité, chrétienté : les LLM en disent aussi long sur notre vision des religions− https://next.ink/253099/islam-judeite-chretiente-les-llm-en-disent-aussi-long-sur-...

LLM Multimodal
9
Mastodon discussion Aug 26

How do micro‑cameras and computer vision hardware change the product roadmap for earbuds and wearables? This article exp...

How do micro‑cameras and computer vision hardware change the product roadmap for earbuds and wearables? This article explores the technical constraints, UX opportunities, privacy i...

Multimodal AI Hardware
18
Mastodon discussion Aug 26

Kimi K3 arrived in July with native vision and a 1M-token context window. The more interesting...#ai #tutorial #opensour...

Kimi K3 arrived in July with native vision and a 1M-token context window. The more interesting...#ai #tutorial #opensource #llm #software #coding #development #engineering #inclusi...

Multimodal
30
Mastodon discussion Aug 26

Want to improve computer vision and object detection models? Expert image annotation provides accurate bounding boxes an...

Want to improve computer vision and object detection models? Expert image annotation provides accurate bounding boxes and consistent labels for high-quality AI training data.Learn ...

Multimodal
24
GitHub Trending repo Aug 26

zidniryi/open-source-ai-models: A curated directory of open-source & open-weight AI models — compare params, VRAM, context length, and license before picking a model for coding, OCR, vision, image generation, speech, reasoning, and RAG.

A curated directory of open-source & open-weight AI models — compare params, VRAM, context length, and license before picking a model for coding, OCR, vision, image generation, spe...

Multimodal RAG Open Source
42
Papers with Code paper Aug 26

GGSS: Geodesic-Gated Spherical Steering for Inference-Time Debiasing of Generative Vision-Language Models

Generative vision-language models (VLMs) are increasingly used in human-centered settings, yet they can produce demographically biased outputs even when images differ only in contr...

Multimodal
21
Mastodon discussion Aug 26

A complete guide to Qwen3.8-27B Uncensored GGUF covering llama.cpp setup, quantization, multimodal support, benchmarks, ...

A complete guide to Qwen3.8-27B Uncensored GGUF covering llama.cpp setup, quantization, multimodal support, benchmarks, use cases and limitations. https://hackernoon.com/qwen38-27b...

Multimodal
9
NewsData.io news Aug 26

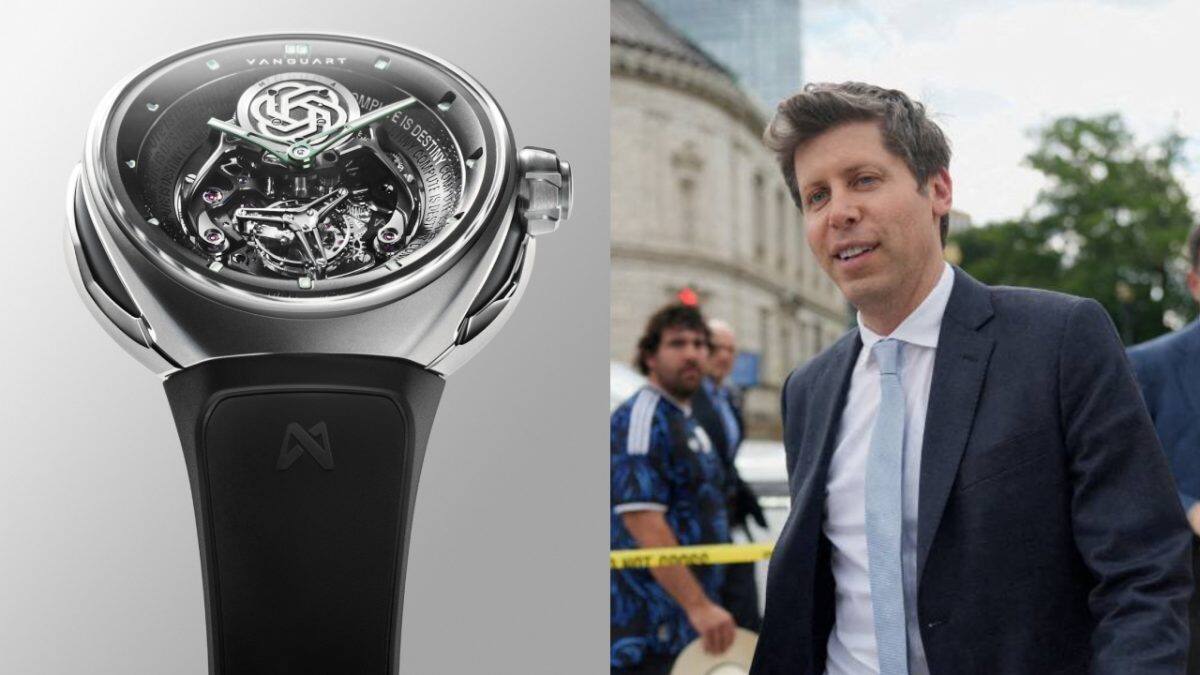
Sam Altman's new luxury watches bring OpenAI's AGI vision to wrist

Sam Altman has reportedly commissioned seven bespoke Vanguart watches carrying OpenAI branding and references to scaling and AGI. Based on a model priced from around $180,000, the ...

OpenAI Multimodal
21
Papers with Code paper Aug 26

MA-VLA: Multi-Arm Vision-Language-Action Model for Collaboration and Compositional Generalization

Multi-arm collaboration is becoming a core capability in embodied manipulation. Recent vision-language-action (VLA) models integrate perception, language, and control, but most rep...

Multimodal
21
Papers with Code paper Aug 26

StreamPI: Streaming Multimodal Temporal Modeling for Vision-Language-Action Models

Vision-Language-Action (VLA) models have demonstrated effectiveness in robot manipulation, yet state-of-the-art models such as pi0.5 operate under a single-frame paradigm, limiting...

Multimodal
21
Papers with Code paper Aug 26

Video-IFBench: Evaluating Instruction Following of Multimodal LLMs in Video Understanding Scenarios

Multimodal Large Language Models (MLLMs) have shown strong performance in video understanding. However, their ability to follow instructions in this domain remains under-explored. ...

Multimodal
21
Papers with Code paper Aug 26

Paint What You See: Benchmarking Dexterous Visual Tool Use in Multimodal Agents

Evaluation is shifting from static QA toward agentic settings where models act through external tools. We identify a critical yet underexplored capability within this space - dexte...

Multimodal Agents
21
Mastodon discussion Aug 26

DeepSeek Adds Vision to V4 Flash, Matches Opus 4.8 on BenchmarksDeepSeek releases V4-Flash-Vision-Exp, a multimodal mode...

DeepSeek Adds Vision to V4 Flash, Matches Opus 4.8 on BenchmarksDeepSeek releases V4-Flash-Vision-Exp, a multimodal model that adds image understanding to its cheap text workhorse ...

Anthropic Multimodal
9
« Previous Page 31 of 99 (2357 items) Next »
AI Hub // AI Intelligence Platform // LIVE FEED // Impressum // Datenschutz © 2026
0 new articles available