/// AI HUB
Dashboard News Models Tools Papers Repos Videos Companies Trending
Login

#Multimodal

2357 articles tagged with Multimodal

Latest Trending
Mastodon discussion Jul 31

Google DeepMind's Gemini Robotics 2 extends its vision-language-action model to control a wide range of robotics platfor...

Google DeepMind's Gemini Robotics 2 extends its vision-language-action model to control a wide range of robotics platforms, from tabletop arms to humanoids, with added higher-level...

Google Multimodal
9
GitHub Trending repo Jul 31

himanshu231204/Microsoft-Azure-AI-103: AI-103T00-A exam prep: study notes for Microsoft Azure AI Engineer certification (34 modules across generative AI, agents, NLP, and computer vision)

AI-103T00-A exam prep: study notes for Microsoft Azure AI Engineer certification (34 modules across generative AI, agents, NLP, and computer vision)

Microsoft Multimodal
35
Mastodon discussion Jul 31

Why I’m excited (and a little uneasy) about Android Halo’s always-on AII love Google’s vision for Android Halo. I don’t ...

Why I’m excited (and a little uneasy) about Android Halo’s always-on AII love Google’s vision for Android Halo. I don’t love how much trust it demands in return.https://www.android...

Google Multimodal
9
GitHub Trending repo Jul 31

bapXai/x8D-Omni-Diffusion: [bapx 2026] x8D-Omni-Diffusion: Unified Multimodal Understanding and Generation with Masked Discrete Diffusion form 8 bit bytes as native tokens

[bapx 2026] x8D-Omni-Diffusion: Unified Multimodal Understanding and Generation with Masked Discrete Diffusion form 8 bit bytes as native tokens

Multimodal
35
YouTube video Jul 31

Chart Deception in Vision-Language Models: From Vulnerability to Mitigation | AI News #Shorts

Chart Deception in Vision-Language Models: From Vulnerability to Mitigation is changing the game. Here's everything you need ...

Multimodal
15
Papers with Code paper Jul 31

WCM: A World Critic Model for Vision-Language-Action Reinforcement Learning

Reinforcement learning (RL) post-training of Vision-Language-Action (VLA) models has shown strong promise for robotic manipulation. Among RL methods, critic-based approaches rely o...

Multimodal
21
Dev.to tutorial Jul 30

Cracking the Pixel Code: How Vision-Driven Agents Translate LLM Thoughts Into DOM Clicks

The bleeding edge of AI automation isn't just about making Large Language Models (LLMs) smarter; it's...

LLM Multimodal
12
Mastodon discussion Jul 30

It’s hard to picture a more nightmarish vision of our #AI future than this…#ElonMusk still thinks there’s a 10 to 20 per...

It’s hard to picture a more nightmarish vision of our #AI future than this…#ElonMusk still thinks there’s a 10 to 20 per cent chance that AI wipes out civilisation, but his “philos...

OpenAI Anthropic Multimodal
24
NewsData.io news Jul 30

Steriline presents OmniAI Vision and OptiLAIN

Steriline is enhancing and strengthening the use of AI in its solutions, and is introducing two intelligent technologies that work in synergy: OmniAI Vision and OptiLAIN.

Multimodal
21
NewsData.io news Jul 30

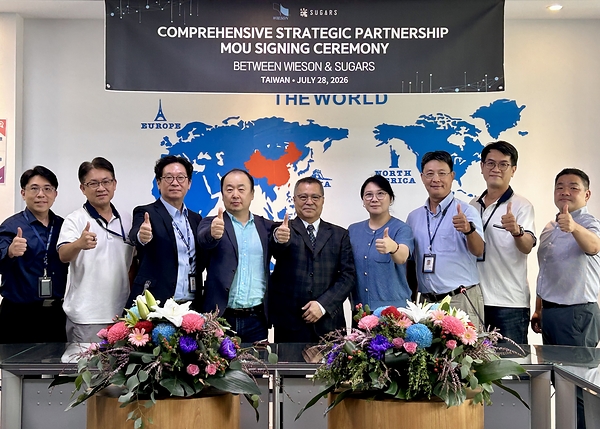
Wieson Technologies Forms Strategic Partnership with Korea's Sugars, Joining Forces to Expand in the Global AI Vision and High-Speed Video Interconnect Market

TAIPEI, July 30, 2026 /PRNewswire/ -- As artificial intelligence advances rapidly, Vision AI has become a core pillar of next-generation applications such as smart vehicles, roboti...

Multimodal
21
Dev.to tutorial Jul 30

How Vision-Language Models Learned to Reason About Space (10 Papers, One Thread)

A guided tour of spatial reasoning in VLMs — from BLINK's perception gap to GR3D — read through one lens: the representational mismatch between language tokens and continuous 3D ge...

Multimodal
12
Papers with Code paper Jul 30

ReToken: One Token to Improve Vision-Language Models for Visual Retrieval

Long visual context poses a challenge for vision-language models: performance degrades as the number of distractors grows, and processing all tokens at once is computationally infe...

Multimodal
21
Papers with Code paper Jul 30

LEDGERMIND: Provenance-Constrained Multimodal Agentic Reasoning with a Structured Evidence Ledger

Multimodal agents for visual question answering increasingly operate as multi-step trajectories that interleave perception, retrieval, and reasoning, yet evaluation still largely r...

Multimodal Agents
21
Papers with Code paper Jul 30

RL^2-VLA: Adaptive RL Latent Compositional Steering with Test-Time Scaling for Vision-Language-Action Models

Despite the impressive visuomotor capabilities enabled by Vision-Language-Action (VLA) models, their performance often degrades on challenging and out-of-domain tasks. Recent test-...

Multimodal
21
Papers with Code paper Jul 30

VAD: Attributing Visual Evidence for Target Reconstruction in Multimodal On-Policy Distillation

Multimodal on-policy distillation (OPD) transfers fine-grained visual knowledge by supervising student-generated trajectories with a privileged-view teacher. Yet its next-token cor...

Multimodal
21
Dev.to tutorial Jul 30

Stop Trading Like It's 1999 — I Built an Autonomous, Vision-Capable Crypto Bot with Python 3.13

Let me tell you a story about failure. December 2024. I'm sitting in my Wrocław apartment after an...

Multimodal
12
Dev.to tutorial Jul 29

Why Your Playwright Tests Keep Breaking (And How Vision LLMs Are Fixing Web Automation Forever)

If you have spent any significant amount of time maintaining end-to-end (E2E) test suites or web...

Multimodal
12
NewsData.io news Jul 29

Mark Zuckerberg outlines vision to put AI superintelligence into everyday life

Mark Zuckerberg says Meta aims to bring AI superintelligence to billions through its apps while debate over user control continues.

Multimodal
21
GNews news Jul 29

Trump’s Unveils Vision For “A New Golden Age” Of Science - Experts Think It Is Anything But

The attacks on science continue, and billions are shifted into artificial "intelligence."

Multimodal
18
NewsData.io news Jul 29

Steriline presents OmniAI Vision and OptiLAIN

A new generation of intelligent technologies that observe, understand and document the process as required by Annex 1 and Annex 22

Multimodal
21
NewsData.io news Jul 29

LEO Technologies Launches Verus Vision AI, Transforming Correctional Cameras into Active Operational Intelligence

AUSTIN, Texas, July 29, 2026 (GLOBE NEWSWIRE) -- LEO Technologies (“LeoTech”) announces the launch of Verus Vision AI, an agentic AI video intelligence solution purpose-built for c...

Multimodal
21
Papers with Code paper Jul 29

TurboVLA: Real-Time Vision-Language-Action Model at 32 Hz on an RTX 4090 with

Vision-language-action (VLA) models commonly adopt an LLM-centric V to L to A pathway, where visual observations are projected into the representation space of a large language mod...

Multimodal
21
Papers with Code paper Jul 29

HumanCLAW: Can Vision-Language Models Act Through a Body?

Evaluating whether a vision-language model (VLM) can act through a physical body is challenging. The outcome of an action couples the VLM's decision with motor control. When a task...

Multimodal
21
Papers with Code paper Jul 29

See2Think: Do Multimodal Models Really Use Intermediate Visual States?

Multimodal large language models increasingly use sketches, annotations, tools, and intermediate images during reasoning, but it remains unclear whether they truly rely on these vi...

Multimodal
21
« Previous Page 44 of 99 (2357 items) Next »
AI Hub // AI Intelligence Platform // LIVE FEED // Impressum // Datenschutz © 2026
0 new articles available