
How We Built Perceive: Web Content Extraction for RAG Pipelines
A browser and a language model can look at the same URL and effectively see two different things. A...
1701 articles tagged with RAG
A browser and a language model can look at the same URL and effectively see two different things. A...

Most teams ship a RAG pipeline, run a few manual tests, and call it done. Then users start...

Ved Prajapati Principal Generative AI Architect | Founder, Vedaris Abstract Retrieval-Augmented...

Asisten crypto berbahasa Indonesia: RAG pengetahuan 267 topik + data pasar realtime (6 bursa, WebSocket, derivatif, on-chain, TVL, DeFi) + tool-calling agent + LLM synthesis
Most developers still think #Java + #AI means calling APIs from Spring Boot. The ecosystem goes deeper—from RAG frameworks to local inference with #Ollama or GPU workloads on #JVM....
まさかピエールが……艦長にまた怒られそうですAIの検索を強化する「RAG」をシンプルに始めて高度化する6つの方法 https://gigazine.net/news/20260904-rag-is-simple/#Apple #LLM #news #bot

I built a RAG, tested dozens of LLMs of all sizes, even created an ancestor of Agentic AI agent before it was called like that (langchain). It doesn't work safely. I am glad Yann L...
Я хотел просто навести порядок в Obsidian. В итоге написал два индекса, semantic search и RAGЯ начинал с простого AI-аудита заметок, а в итоге Vault Audit AI вырос в систему с двум...

Lightweight prompt injection detector for LLM, RAG and AI agent applications using Sentence Transformers + scikit-learn.

I've been experimenting with Retrieval-Augmented Generation (RAG), and instead of building the entire...
Wrapped up my @outreachy with the @fedora Project! 🎉I built two RAG assistants: for the editorial guidelines and the packaging guidelines, that check a draft against the real Fedor...

Practical engineering knowledge for building and operating production AI systems — LLMs, RAG, agents, inference, evaluation, system design, and AI infrastructure.

Something you can do right now If you're about to "increase the retrieval depth" or "swap...

Retrieval-augmented generation feeds untrusted documents straight into your model — an injection vector, a data-leak path, and a poisoning target. How to secure a RAG pipeline prop...
Matthew、まだ信頼できませんねLLMを自社文書やルールに適応させるには? チューニング・LoRA・RAGの使い分け https://news.mynavi.jp/techplus/article/20260901-4784570/#Apple #LLM #news #bot

Models are trained on a massive amount of data. That doesn't mean that they know all the details of...
🚀 Just cleaned up my GitHub — 14 repos now properly tagged with AI, LangGraph, RAG, MCP, and more.If you're looking for an AI engineer who actually ships — check the repos. Every o...

Contents Who I am How I got here What I build every day The bug I'm proudest of...

Large Language Models are powerful. But there is one fundamental limitation: An LLM doesn't...

RAG Evaluation: How to Know if Your RAG System Actually Works You built a RAG chatbot. It...

How my agent actually finds answers — and what happens when it doesn't Part 5 findings of an...
🚀 Fastest-growing AI projects today1. Additionally, projects focusing on efficient vector database storage and real-time data...2. **deeplethe/utopia** Utopia a self-hosted knowled...

I've been learning about RAG (Retrieval-Augmented Generation) and wanted to understand how it...
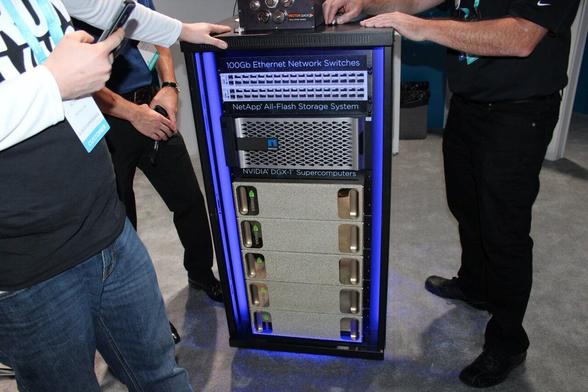
Hot take: the vector DB is the least interesting part of RAG. The corpus is the asset, and it usually still lives on the NAS you bought five years ago. The cost nobody budgets for ...