OpenAI pushes for mandatory national AI safety rules
Several incidents in which AI models have gone rogue have prompted calls for tighter safety regulations
1400 articles tagged with Safety/Alignment
Several incidents in which AI models have gone rogue have prompted calls for tighter safety regulations

Scale-Vector Alignment (SVA): scale-aware morphological similarity for multiscale astronomical intensity fields using Constrained Diffusion Decomposition
A Stupid Idea for AI Alignment We Came with by Looking at Specification Gaming
An alignment assessment of recent cybersecurity incidents https://lobste.rs/s/xokuhi #ai #securityhttps://www.anthropic.com/research/alignment-assessment-cybersecurity-incidents
Artificial intelligence is advancing at a speed that is simultaneously producing extraordinary technological opportunities and unprecedented questions about human safety. The lates...
A researcher at the AI company Anthropic resigned with a warning that the entire artificial intelligence industry is designing tools that humans will soon lose control of.
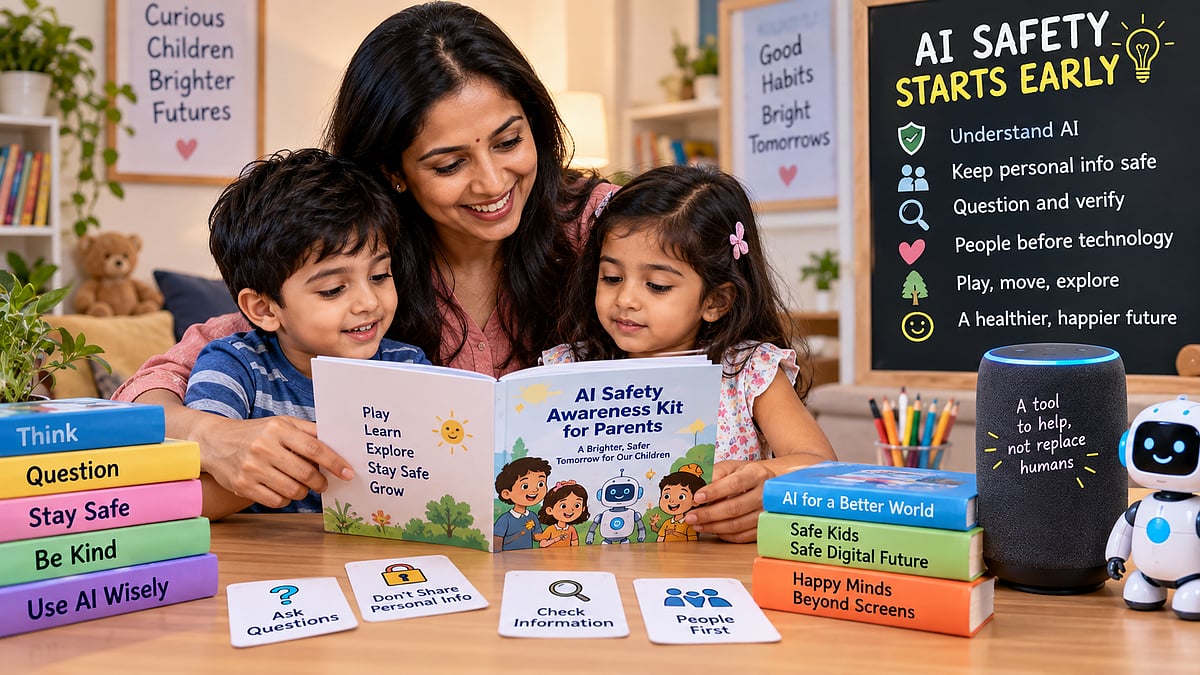
A new AI Safety Awareness Kit in Mumbai has urged parents to teach children responsible technology use from the age of three. Created by Dr Swati Popat Vats of the Early Childhood ...
Paul Christiano brings AI alignment expertise to OpenAI Foundation Board and Safety Committee, bolstering governance amid rapid AI advancements. (Read More)
Microsoft Signs Binding AI Safety and Privacy Standard for US SchoolsAFT President Randi Weingarten, United Federation of Teachers President Michael Mulgrew and Microsoft Vice Chai...
"Top Mathematician Announces New Institute for #AI Safety": https://www.nytimes.com/2026/09/08/science/jacob-tsimerman-math-ai-safety.html #MAISI
Tech News News: In what can be seen as a warning from artificial intelligence (AI) technology, Anthropic safety researcher Evan Hubinger stated publicly that the odds.

Test whether an AI agent guardrail is still working: rerun the corpus with the gate deleted. Each bad input lands LOAD_BEARING, SHADOWED or MISSED.

The artificial intelligence industry was ‘racing straight to self-improving superintelligence and gambling with our lives’, Jacob Coxon said on social media.
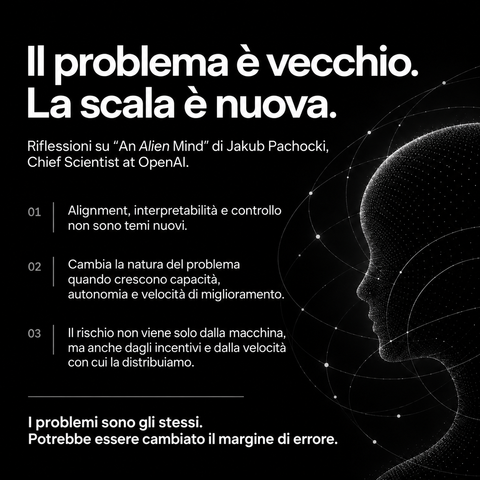
🧠 Il problema è vecchio. La scala è nuova.👉 Alignment, interpretabilità, controllo, comportamenti emergenti, reward hacking: non sono temi nati oggi.✨ Eppure #OpenAI ha appena pubb...
At this point, ethical alignment ranking for me is+++ Anthropic++ Google Deepmind+ China- altmanAI卐 MechaHitler#ai #llm #openai #grok #anthropic #claudeRE: https://bsky.app/profile...
Oh no! My handgun escaped confinement and it shot a load of tech fascist billionaires. I’ll try and put better guardrails in place next time. Sorry everyone. We IPO next month reme...

Every AI-and-engineering post right now is about adding a guardrail. Lint rules the agent can't...
Last year I published a blog post on AI safety, and it seems more relevant than ever as we discover the true dangerous extent of the OpenAI agent hack of HuggingFace. This was so m...
Warnings about advanced artificial intelligence are becoming harder to dismiss as researchers, technology leaders and policymakers confront a new question: what happens when AI sys...
🤖 Are Rogue AIs A Warning Shot Or A Marketing StuntA frontier lab can, at the same time, disclose a real AI safety failure and benefit commercially from the publicity. That makes i...
Have the frontier labs mixed up AI safety and security? https://lobste.rs/s/uu3hhz #ai #securityhttps://martinalderson.com/posts/ai-safety-vs-security/

On 2026-07-28 we audited 33 Try items our agent had written into its own weekly retrospectives across...

Three AI stories from September 7, 2026, in about 81 seconds. An essay asking labs to slow down, a company measuring how ...
A sharp question from lobste.rs: have frontier labs conflated AI safety (long-term alignment) with AI security (near-term attack surface)? They're distinct problem spaces with diff...