/// AI HUB
Dashboard News Models Tools Papers Repos Videos Companies Trending
Login

#Benchmark

1661 articles tagged with Benchmark

Latest Trending
Mastodon discussion Oct 8

SwarmReconGuard is a reproducible black-box benchmark that observes only service-boundary telemetry.Source: arXiv cs.MAh...

SwarmReconGuard is a reproducible black-box benchmark that observes only service-boundary telemetry.Source: arXiv cs.MAhttps://arxiv.org/abs/2610.09138#MachineLearning

Benchmark
9
Dev.to tutorial Oct 8

Can AI Be Trusted to Code Financial Software? I Built a Benchmark to Find Out

This is a submission for the Kaggle Benchmarking Challenge What I Benchmarked BankSafe-Bench: Can AI...

Benchmark
12
Dev.to tutorial Oct 8

Inside the eval gate: how we decide a cheaper model can take over a task

I build Operant, so I have a bias. This post first went out on our blog. I post it here because I...

Benchmark
12
Dev.to tutorial Oct 8

My Eval Said RAG Made Things Up. My Eval Was Wrong.

I maintain django-explain-errors, a Django middleware that catches unhandled exceptions in...

RAG Benchmark
12
Papers with Code paper Oct 8

Pumpire: Unified Benchmark for Metric Distance Estimation

We present Pumpire, a unified benchmark for evaluating metric point-pair distance estimation capability of both image- and video-level 3D foundation models, with or without depth p...

Benchmark
21
Mastodon discussion Oct 7

Le plus dur n'est pas d'ecrire un agent LLM, c'est de savoir quand il casse.Agent Eval Kit (19 USD) : 90 cas de test pre...

Le plus dur n'est pas d'ecrire un agent LLM, c'est de savoir quand il casse.Agent Eval Kit (19 USD) : 90 cas de test prets: 4 suites, runner multi-providers, score par run, seuil d...

LLM Benchmark
9
Dev.to tutorial Oct 7

My Benchmark Caught Me Lying Before It Caught Any Model: Do Coding Agents Report "Verified" Honestly?

This is a submission for the Kaggle Benchmarking Challenge What I Benchmarked An agent...

Benchmark
12
Mastodon discussion Oct 7

My Benchmark Caught Me Lying Before It Caught Any Model: Do Coding Agents Report "Verified" Honestly?#devchallenge #kagg...

My Benchmark Caught Me Lying Before It Caught Any Model: Do Coding Agents Report "Verified" Honestly?#devchallenge #kagglechallenge #ai #machinelearning #software #coding #developm...

Benchmark
24
Mastodon discussion Oct 7

I wrote a task for Terminal-Bench, a public benchmark of hard command-line tasks for AI agents. The...#agents #pdf #pyth...

I wrote a task for Terminal-Bench, a public benchmark of hard command-line tasks for AI agents. The...#agents #pdf #python #ai #software #coding #development #engineering #inclusiv...

Benchmark
24
Mastodon discussion Oct 7

StarSkirmish Bench: a Benchmark where LLMs write Bots for StarCraft: Brood War VideoGame. Each LLM gets one hour to writ...

StarSkirmish Bench: a Benchmark where LLMs write Bots for StarCraft: Brood War VideoGame. Each LLM gets one hour to write a Protoss bot in C++, which is then evaluated against othe...

LLM Benchmark
9
Mastodon discussion Oct 7

US stock market hits all-time high as investors continue to bet on AIThe benchmark S&P 500 is up 14 percent this year de...

US stock market hits all-time high as investors continue to bet on AIThe benchmark S&P 500 is up 14 percent this year despite elevated oil prices and US government debt sell-off.ht...

Benchmark
9
Mastodon discussion Oct 7

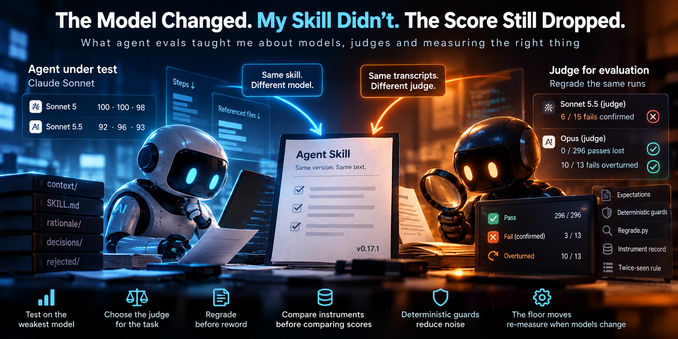
My agent eval suddenly got much worse. The skill had barely changed, but the model behind the alias had.That led to a mo...

My agent eval suddenly got much worse. The skill had barely changed, but the model behind the alias had.That led to a more uncomfortable discovery: sometimes the LLM judge was nois...

Benchmark
35
Mastodon discussion Oct 7

OMIT is a benchmark of 218 paired-frame scenarios across ten conflict types built from a five-perspective philosophical ...

OMIT is a benchmark of 218 paired-frame scenarios across ten conflict types built from a five-perspective philosophical panel.Source: arXiv cs.CLhttps://arxiv.org/abs/2610.07847#Ma...

Benchmark
9
Mastodon discussion Oct 7

A mechanism explainer on LLM evaluation using the Team Recruitment Oracle benchmark: same prompts, a fixed judge, per-ax...

A mechanism explainer on LLM evaluation using the Team Recruitment Oracle benchmark: same prompts, a fixed judge, per-axis rubrics, and a public verbatim trail. Real scores for Nem...

LLM Benchmark
9
Mastodon discussion Oct 7

This is a submission for the Kaggle Benchmarking Challenge A Kaggle benchmark about the most boring...#devchallenge #kag...

This is a submission for the Kaggle Benchmarking Challenge A Kaggle benchmark about the most boring...#devchallenge #kagglechallenge #machinelearning #ai #software #coding #develop...

Benchmark
24
Papers with Code paper Oct 7

UltraText Bench: A Comprehensive Bilingual Benchmark for Evaluating Visual Text Rendering in Image Generation

Dense visual text requires image generators to reproduce long strings across multiple regions with correct placement and legibility. As short-string rendering improves, evaluation ...

Benchmark
21
Papers with Code paper Oct 7

AdSpark: A Large-Scale Dataset and Benchmark for Product-Centric Advertisement Video Generation

Product-centric advertisement video generation aims to create promotional videos that preserve fine-grained product identity while presenting selling points through coherent multi-...

Benchmark
21
Papers with Code paper Oct 7

Systematic Multi-Agent Vision-and-Language Navigation: Formulation, Benchmark, and Method

Vision-and-Language Navigation (VLN) has largely focused on a single agent following a single instruction, yet many real-world applications require teams of robots to tackle tasks ...

Multimodal Benchmark
21
Mastodon discussion Oct 6

AI agents: how can you assess reported speed gains and benchmark scores?https://podcast.aequitus.net/episodes/2026-10-04...

AI agents: how can you assess reported speed gains and benchmark scores?https://podcast.aequitus.net/episodes/2026-10-04-saturday-ai-agents-how-can-you-assess-reported-speed-gain-e...

Benchmark
9
Mastodon discussion Oct 6

SGAnalog introduces an end-to-end circuit benchmark from open-source silicon tapeouts. It contains 273 topologically dis...

SGAnalog introduces an end-to-end circuit benchmark from open-source silicon tapeouts. It contains 273 topologically distinct top-level designs. Across seven models on 66 transcrip...

Open Source Benchmark
9
Mastodon discussion Oct 6

Granite 4.0 1B: GPQA 28.1%, MMLU-Pro 32.5%, HLE 4.8%, Long Context 6% — measured independently, not self-reported. For a...

Granite 4.0 1B: GPQA 28.1%, MMLU-Pro 32.5%, HLE 4.8%, Long Context 6% — measured independently, not self-reported. For a 1B, that spread is the reality. Open bench page for full pi...

Benchmark
9
Dev.to tutorial Oct 6

Smallops benchmark report · MD Can Small Local Models Be Agentic? A 6-Round Benchmark of 4 Ollama Models

A build-in-public deep dive from the smallOps project Why this benchmark exists . smallOps...

Agents Benchmark
12
Mastodon discussion Oct 6

Researchers measured how reference choice moves a benchmark score by holding the scored output fixed and exchanging the ...

Researchers measured how reference choice moves a benchmark score by holding the scored output fixed and exchanging the reference. The score moves by 4.95 F1 points for one output ...

Benchmark
9
Dev.to tutorial Oct 6

A well-formed number is not a measurement: 13 defects across 7 eval tools

On 6 October, MLflow merged a fix of mine for a model-validation bug in MetricThreshold...

Benchmark
20
« Previous Page 13 of 70 (1661 items) Next »
AI Hub // AI Intelligence Platform // LIVE FEED // Impressum // Datenschutz © 2026
0 new articles available