
AI pair-programming became useful when every idea met a benchmark
The most confident optimization suggestions were not always the useful ones. An 8 by 8 register...
1676 articles tagged with Benchmark
The most confident optimization suggestions were not always the useful ones. An 8 by 8 register...
📊 Nova 2.0 Lite (Non-reasoning) — the actual numbers GPQA: 60.3% MMLU-Pro: 74.3% Humanity's Last Exam: 2.9% Long Context Reasoning: 18.7%⚡ 226.5 tokens/sec💰 10.2 intelligence point...

Reference-to-video (R2V) generation is evolving toward increasingly general and versatile reference control, giving rise to the emerging paradigm of omni R2V generation. However, e...
AI Hacking RaceA benchmark of verified command execution in isolated test targets.https://enclave.ai/hackingrace#ai #cybersecurity #infosec #security
I added a WebMCP benchmark to DeepDeck, my MIT-licensed macOS desktop project built on DeepSeek...#webdev #tutorial #ai #testing #software #coding #development #engineering #inclus...
A new benchmark evaluates open-source instruction-tuned LLMs for key-value pair extraction under clean-text and noisy OCR conditions. Results show performance degrades substantiall...
Codex and Claude Code: one benchmark run isn't enoughA new arXiv preprint finds AI coding agents like Codex and Claude Code are too stochastic for single benchmark runs, affecting ...
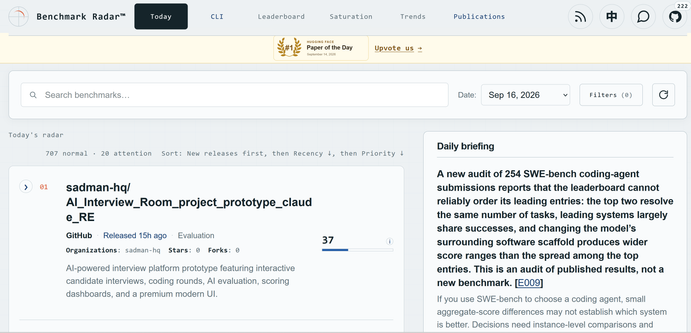
"Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation"We release the web dashboard with a benchmark leaderboard, a Pareto frontier view of score ag...

Question answering has advanced rapidly with large language models, but predominantly for high-resource languages, in both text and spoken settings. Spoken question answering (SQA)...

Telecom fraud scripts evolve rapidly and are often designed to resemble routine service conversations, creating two key requirements for audio-based telecom-fraud evaluation. First...
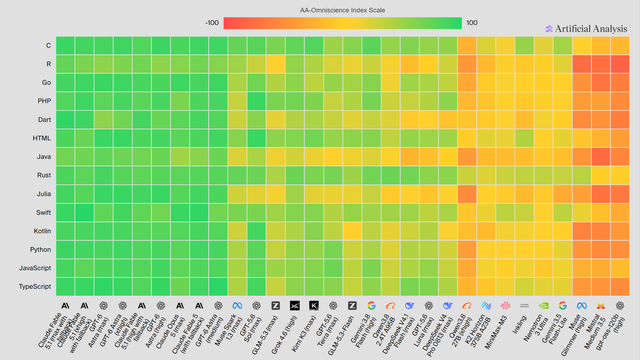
Okay, the breakdown *by-language* of Artificial Analysis's "Omniscience" hallucination/capability benchmark is absolutely fascinating.I feel like this is some of the first concrete...
拒否ルールを全部消しても、Claude Code は eval を止めた。守っていたのは別の仕組みだったhttps://qiita.com/suwa_nobu/items/5145961004e38e2fe316?utm_campaign=popular_items&utm_medium=feed&utm_source=popular_items#qiita...
いつの間にか、カンナが僕よりAI Demandについて詳しくなってましたですM6 Chip Benchmark Surfaces Ahead of New Mac Mini Launch Next Week https://www.macrumors.com/2026/09/15/apple-m6-chip-benchmark/#Apple #LLM #ne...
M6 Chip Benchmark Surfaces Ahead of New Mac Mini Launch Next WeekThe first unverified benchmark result for Apple's new M6 chip surfaced in the Geekbench 7 database today, offering ...
📊 Qwen3 Omni 30B A3B Instruct: 62% GPQA, 72.5% MMLU-Pro, but 0% on long-context reasoning. At 108.2 tokens/sec and 14 intel points per dollar, independently measured → see the raw ...
Mac Studioはタムズにいくらでもあったんですが……M5 Ultra Chip's Impressive Performance Boost Revealed in First Benchmark Result https://www.macrumors.com/2026/09/15/apple-m5-ultra-chip-benchmark/#App...
1Password's AI patching benchmark is misleading https://lobste.rs/s/qx8dxe #ai #practices #securityhttps://blog.trailofbits.com/2026/09/15/1passwords-ai-patching-benchmark-is-misle...

An agent evaluation set starts healthy. It contains the obvious intents, a few tool failures, and the...
Nobody publishes a leaderboard for the metrics that actually matter: cost per successful task, recovery rate after a failure, and how often a human accepts the output. Those are th...
Mizan is Iraq's national benchmark evaluating LLMs on Iraqi Arabic and the Iraqi civic context across six axes. A pilot evaluation of 27 systems reveals the Iraqi track discriminat...
A clinical agent benchmark can report identical verdicts on identical inputs while filing materially different orders on each run.Source: arXiv cs.CLhttps://arxiv.org/abs/2609.1358...
Researchers introduced a paired benchmark to measure outcome-conditioned shifts in clinical temporal reasoning. Full timeline exposure produces hindsight-sensitive shifts across mo...
An operational triage benchmark showed where a local LLM beat deterministic rules — and where it didn't. The result led to a hybrid architecture with human review and an audit trai...
MulRobBench is introduced as a decision-level benchmark for safe and security-policy-compliant multimodal UAV agents.Source: arXiv cs.MAhttps://arxiv.org/abs/2607.23870#MachineLear...