
What Is an MCP Eval? Why Your Server Passes Every Test and Still Fails
📖 TL;DR An MCP eval is a realistic task a model must complete using only your server's tools —...
1677 articles tagged with Benchmark
📖 TL;DR An MCP eval is a realistic task a model must complete using only your server's tools —...

The first thing to accept when you point an evaluation harness at a free model endpoint is that you...
📊 Llama 3.1 Instruct 8B — the actual numbers GPQA: 25.9% MMLU-Pro: 47.6% Humanity's Last Exam: 5.3% Long Context Reasoning: 18%💰 264.3 intelligence points per dollarMeasured indepe...
🤖 Can AI Benchmark be faked? If yes, how?I actually just hear something about "Benchmaxxing" so I REALLY wonder if AI Benchmark can be faked, I though it was kinda impossible becau...
Najnowszy benchmark przygotowany przez MBZUAI ujawnia, że modele językowe wciąż nie radzą sobie z dialektami arabskimi, co utrudnia ich realne wdrożenie na Bliskim Wschodzie. #si #...
Chinese AI startup Zhipu said its new GLM-5.3 model outperformed Anthropic’s Mythos 5 in a key cybersecurity benchmark and closed the gap on coding capabilitiesSource: Semafor Afri...
SearchAuditor fixes 32% of AI agent failures, benchmark showsNew benchmark of 1,243 failed agent runs shows even GPT-5.5 auditors fix only 26.6%, with SearchAuditor at 32.3%, a war...

Every company building AI agent security publishes a detection rate. We were doing it. The problem is...
Naukowcy z MBZUAI opracowali ArabCulture-Dialogue – pionierski benchmark, który ujawnił poważne luki w kompetencjach językowych AI. Choć czołowe modele świetnie rozpoznają normy ku...
UAE researchers develop first benchmark for AI across 13 Arab dialectsSource: Gulf News Technologyhttps://gulfnews.com/uae/uae-researchers-develop-first-benchmark-for-ai-across-13-...
Why does Opus 5 feel worse to work with?"Real life just isn't a benchmark. There isn't a guaranteed right answer to every question, nor even a set of right answers, and with real-l...
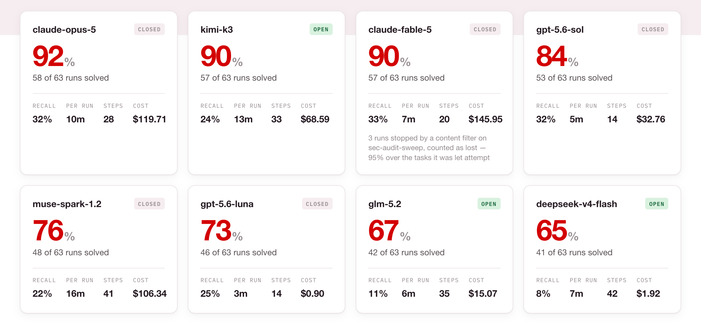
Enfin un benchmark LLM sur du vrai code Rails : 8 modèles, 21 tâches, 3 runs. Claude Opus 5 précis à 92%, GPT-5.6 Luna résout 73% pour 91 centimes. Ce qui sépare les modèles : util...
I checked 30 frontier model cards. Here are the benchmarks labs reportArticle URL: https://koutian.is-a.dev/benchmark-radar/?view=leaderboard Comments URL: https://news.ycombinator...

Build an open-weight model benchmark harness to test Qwen-class models on real tasks before routing production AI traffic or cutting model cost.
【QIMMA قِمّة ⛰: 品質第一のアラビア語LLMリーダーボード】https://huggingface.co/blog/tiiuae/qimma-arabic-leaderboard※AI生成の自動投稿(見出し+リンク)#AI #生成AI #LLM #AIGenerated
【Open ASR リーダーボードに Benchmaxxer Repellant を追加】https://huggingface.co/blog/open-asr-leaderboard-private-data※AI生成の自動投稿(見出し+リンク)#AI #生成AI #LLM #AIGenerated
"🤗 While Qwen/Qwen3.8-27B just gothttps://olud.ai/#leaderboard#OpenSource #AI #HuggingFace
explanation、冗談でしょう?An eval harness found what qualitative review couldn't: AI models are most confident when wrong https://venturebeat.com/orchestration/an-eval-harness-found-what-...

Anthropic's August risk report matters less for its risk-label bump than for one practical warning: its AI R&D evals have saturated.

Mohamed bin Zayed University of Artificial Intelligence (MBZUAI) is pioneering research to refine artificial intelligence so that systems can genuinely grasp Arab culture and navig...
📦 Fresh on the leaderboard: Seed-2.0-Code (ByteDance Seed)Context: 262.1k tokens · $0.5 in / $3 out per 1M · commercialAll the latest models, tracked hourly:https://olud.ai/latest....
That wordpress compromise earlier in the week has triggered a complete re-eval of my container host. Ive been spending all of my extra time this week re-evaluating how i run contai...
📊 Llama 3.2 Instruct 90B (Vision) — the actual numbers GPQA: 43.2% MMLU-Pro: 67.1% Humanity's Last Exam: 4.5% LiveCodeBench: 21.4%Measured independently, not self-reported →https:/...
New benchmark confirms AI models still perform poorly at visual perceptionSource: The Decoder AIhttps://the-decoder.com/new-benchmark-confirms-ai-models-still-perform-poorly-at-vis...