
RAG without a vector database: fastembed + numpy, cosine by hand
title: RAG without a vector database: fastembed + numpy, cosine by hand published: false description:...
1697 articles tagged with RAG
title: RAG without a vector database: fastembed + numpy, cosine by hand published: false description:...

Why retrieval quality, document structure, and relevance matter more than adding a model to your...
Локальный ИИ-ассистент по базе знаний компании: RAG поверх вики, файлов, 1С и Битрикс24В любой компании старше пары лет знания размазаны по вики, папкам с регламентами, почтовым пе...

🐋 Полный гайд на русском: как установить и запустить DeepSeek локально (V4, R1) на ПК, Mac и сервере — Ollama, llama.cpp, LM Studio, vLLM, Open WebUI, API, RAG, агенты, fine-tuning...
RAG vs. Fine-Tuning vs. Prompt Engineering: Stop Picking the Wrong OneA decision framework for people who actually need results. When to use RAG, when to fine-tune, when to just pr...

Most RAG tutorials end when the chatbot answers a question about a PDF. I wanted to find out what...

Getting an AI app to answer a question is exciting. Getting it to recognize when the documents don’t...
#AIEngineering #llm #tuning #llmraghttps://machinelearningmastery.com/rag-vs-fine-tuning-for-domain-adaptation-when-to-use-which/
💥 Common RAG mistakes I see in production:❌ Retrieving too many chunks (bloats context, adds noise)❌ No re-ranking (BM25 + semantic hybrid is better)❌ Ignoring metadata filtering (...
A common gotcha with RAG configurations: the relevance threshold filter only applies when using semantic search or reranking modes. If you’re running plain keyword matching, adjust...
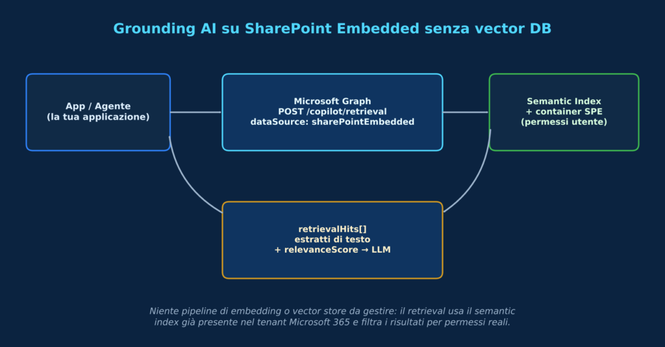
Grounding AI su SharePoint Embedded: come fare RAG senza creare un vector database Microsoft 365 Copilot Retrieval API permette di costruire agenti AI con grounding sui documenti d...
Первый RAG комом: как мы учились анализировать ошибки автотестов с помощью LLMПривет! Меня зовут Алексей, я автотестер в hh.ru . У нас около 3000 запускаемых классов с e2e (UI) тес...

When Perplexity, ChatGPT search or Google's AI features answer a question, they don't read your page...

Fixed token windows cut functions in half. A runnable tree-sitter chunker that splits Python by function and class, scored against plain token windows.

This is a submission for the Hacktoberfest Open-Source AI Challenge Week 2: Side Hustle ...
Running RAG with a (small) language model in the browser https://lobste.rs/s/nsjjo3 #ai #javascript #webhttps://bart.degoe.de/rag-with-a-small-language-model-in-the-browser/
Комнатный RAG: бесплатный ИИ-помощник-консультант по содержимому сайтаМожно ли превратить обычный сайт небольшой компании в ИИ-консультанта и уложиться в бесплатные квоты хостинга?...
Как сделать RAG-чат для сайта, который не выдумывает цены: пять решений из моего ботаС июня я делаю AI-чат для сайтов, который не выдумывает цены и не соглашается с клиентом во всё...
Digital identities don’t just break inside #LLM or RAG pipelines.We see them fracture along analytical fault lines.Reconstruction Failure Modes:Referential Reconstruction Failures–...

RAG — Retrieval-Augmented Generation A deep-dive walkthrough of Retrieval-Augmented...
Ошибки RAG: 6 причин, почему лагает память ИИ-агента, и как провести диагностику retrievalRAG (Retrieval-Augmented Generation или генерация с дополненной выборкой) — это технология...

A few weeks ago MicroLLM lab was featured in Hacker Newsletter. It shows off how you can run small...

Agent memory research surges this week while a placebo-controlled study pokes real holes in RAG's structure-aware chunking lore.

Embeddings & Vector Search A deep-dive walkthrough of embeddings and vector search —...