/// AI HUB
Dashboard News Models Tools Papers Repos Videos Companies Trending
Login

#Fine-Tuning

322 articles tagged with Fine-Tuning

Latest Trending
Dev.to tutorial Oct 7

How LoRA Actually Works: Low-Rank Decomposition, Weight Merging, and Memory Breakdown Under the Hood

Why full fine-tuning an 8B model requires 130+ GB VRAM, how low-rank matrix decomposition cuts parameters by 99%, and how weight merging enables zero-latency serving.
Fine-Tuning
12
Mastodon discussion Oct 7

How LoRA Actually Works: Low-Rank Decomposition, Weight Merging, and Memory Breakdown Under the HoodIf you try to full-p...

How LoRA Actually Works: Low-Rank Decomposition, Weight Merging, and Memory Breakdown Under the HoodIf you try to full-parameter fine-tune an 8-billion parameter language model in ...

Fine-Tuning
30
Mastodon discussion Oct 7

Anker’s 100W universal charger is a great travel gadget for $64The Anker Nano 100W travel adapter with its folding prong...

Anker’s 100W universal charger is a great travel gadget for $64The Anker Nano 100W travel adapter with its folding prongs. | Image: Anker For frequent travelers who like to pack li...

Google Fine-Tuning
18
Mastodon discussion Oct 3

TL;DR: A PEFT LoRA adapter can give individual modules their own rank and alpha through rank_pattern...#llm #vllm #lora ...

TL;DR: A PEFT LoRA adapter can give individual modules their own rank and alpha through rank_pattern...#llm #vllm #lora #selfhosted #software #coding #development #engineering #inc...

LLM Fine-Tuning
24
Mastodon discussion Oct 2

A new method purifies LoRA-tuned LLMs via null-space projection without requiring trigger knowledge or retraining.Source...

A new method purifies LoRA-tuned LLMs via null-space projection without requiring trigger knowledge or retraining.Source: arXivhttps://arxiv.org/abs/2610.00685#MachineLearning

Fine-Tuning
9
Mastodon discussion Oct 1

Ever wonder what actually happens inside an LLM? KV Cache, Flash Attention, Speculative Decoding, LoRA — LLM Internals b...

Ever wonder what actually happens inside an LLM? KV Cache, Flash Attention, Speculative Decoding, LoRA — LLM Internals by breaks it all down with numeric examples, not hand-waving....

LLM Fine-Tuning
9
Mastodon discussion Sep 30

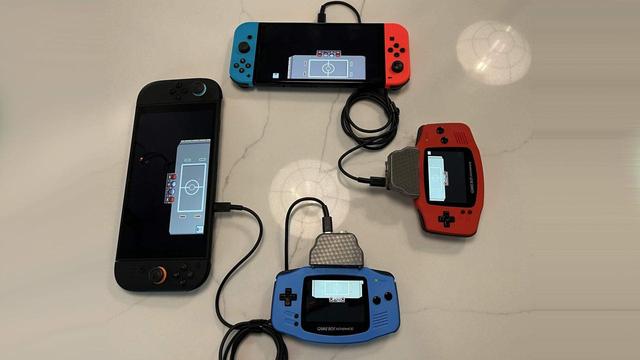
🕹️ RetroSync Adapter For Switch To GBA Trading & Battling Is Releasing This December🤝Like our website? Support us as an ...

🕹️ RetroSync Adapter For Switch To GBA Trading & Battling Is Releasing This December🤝Like our website? Support us as an independent publisher by tipping, joining our paid community...

Fine-Tuning
9
Papers with Code paper Sep 29

Transformers Stop Thinking Too Early, and a Tiny LoRA Fixes It

Pretrained transformers use little of their depth to follow references in context. Thirteen base models reliably follow only 1.4-3.6 lines, and extra pretrained loops add little. A...

Fine-Tuning
21
Mastodon discussion Sep 28

OWC Thunderbolt Dual DisplayPort Adapterですか……タムズの次の仕事になりそうですLast Chance: OWC's Best Mac Accessories Are on Sale Just for...

OWC Thunderbolt Dual DisplayPort Adapterですか……タムズの次の仕事になりそうですLast Chance: OWC's Best Mac Accessories Are on Sale Just for MacRumors Readers https://www.macrumors.com/2026/09/28/last...

Fine-Tuning
27
Papers with Code paper Sep 28

PReCache: Efficient KV Cache Sharing for Multi-LoRA Agents via Low-Rank Precomputation and Neutral Reconstruction

Multi-LoRA agent systems enable efficient role specialization by sharing a common backbone model. However, each agent repeatedly processes the growing shared trajectory and constru...

Fine-Tuning
21
Mastodon discussion Sep 27

https://techcrunch.com/2026/05/28/rsi-is-the-new-agi-and-its-just-as-hard-to-pin-down/#AI #RSI #lora

https://techcrunch.com/2026/05/28/rsi-is-the-new-agi-and-its-just-as-hard-to-pin-down/#AI #RSI #lora

Fine-Tuning
9
Hugging Face model Sep 27

pablodawson/MiniMax-H3-360-Orbit-LoRA - image-text-to-video

Hugging Face model: pablodawson/MiniMax-H3-360-Orbit-LoRA

Video Generation Fine-Tuning
79
Dev.to tutorial Sep 26

LoRA & DoRA: The Math, Memory, and Trade-offs

LoRA and DoRA explained: matrix shapes, the geometry of weight decomposition, exact memory math for a 27B model, and what the DoRA benchmarks support.

Fine-Tuning
12
Mastodon discussion Sep 26

LoRA and DoRA explained: matrix shapes, the geometry of weight decomposition, exact memory math for a 27B model, and wha...

LoRA and DoRA explained: matrix shapes, the geometry of weight decomposition, exact memory math for a 27B model, and what the DoRA benchmarks support.#machinelearning #ai #llm #dee...

Fine-Tuning
24
GitHub Trending repo Sep 25

neurono-ml/typed-lm: Single-forward-pass semantic routing in Rust: turn dense LLMs (Llama, Qwen, Mistral, Gemma) into a typed decision API with LoRA/QLoRA training and FP8/FP4 quantization, built on Candle.

Single-forward-pass semantic routing in Rust: turn dense LLMs (Llama, Qwen, Mistral, Gemma) into a typed decision API with LoRA/QLoRA training and FP8/FP4 quantization, built on Ca...

Google Mistral Fine-Tuning
42
Hugging Face tool Sep 25

hugging-apps/minimax-h3-character-swap-lora - AI Space/Demo

Hugging Face Space: hugging-apps/minimax-h3-character-swap-lora

Fine-Tuning
67
Hugging Face model Sep 25

akatz-ai/MiniMax-H3-Character-Swap-LoRA - video-to-video

Hugging Face model: akatz-ai/MiniMax-H3-Character-Swap-LoRA

Fine-Tuning
82
Mastodon discussion Sep 24

Learn how FaceSwap_MiniMaxH3_REF2VA works, including its MiniMax H3 compatibility, Faceswap trigger word, LoRA strength,...

Learn how FaceSwap_MiniMaxH3_REF2VA works, including its MiniMax H3 compatibility, Faceswap trigger word, LoRA strength, and limitations. https://hackernoon.com/faceswap-minimax-h3...

Fine-Tuning
9
Dev.to tutorial Sep 20

MCP Is an Adapter Layer, So Version the API First

If an MCP server is usually a thin layer over an API, the practical takeaway is simple: treat the API...

Fine-Tuning MCP API
12
Hugging Face tool Sep 18

glitchlab/MiniMax-H3-Turbo-Lora-UNCENSORED-Workflow - AI Space/Demo

Hugging Face Space: glitchlab/MiniMax-H3-Turbo-Lora-UNCENSORED-Workflow

Fine-Tuning
68
Dev.to tutorial Sep 17

🚀 bro.js v2.4.5 – Next.js Adapter & AI‑First DX

Hey devs! 🎉 I’m super excited to share bro.js v2.4.5 – the biggest leap we’ve made yet. Imagine...

Fine-Tuning
12
Mastodon discussion Sep 16

CoSQ is a prompt-only framework that makes LLM answer commitment conditional on explicit information checks, no fine-tun...

CoSQ is a prompt-only framework that makes LLM answer commitment conditional on explicit information checks, no fine-tuning required.#agents #ai #llm #software #coding #development...

LLM Fine-Tuning
24
Dev.to tutorial Sep 14

How I Fine-Tuned a 7B LLM with LoRA and Unsloth

How I Fine-Tuned a 7B LLM with LoRA and Unsloth When I was working on Khatta-ka-LLM, two...

LLM Fine-Tuning
12
Mastodon discussion Sep 14

How I Fine-Tuned a 7B LLM with LoRA and Unsloth When I was working on Khatta-ka-LLM, two...#ai #machinelearning #llm #pa...

How I Fine-Tuned a 7B LLM with LoRA and Unsloth When I was working on Khatta-ka-LLM, two...#ai #machinelearning #llm #pashto #software #coding #development #engineering #inclusive ...

LLM Fine-Tuning
24
« Previous Page 3 of 14 (322 items) Next »
AI Hub // AI Intelligence Platform // LIVE FEED // Impressum // Datenschutz © 2026
0 new articles available